Presents
Magnus Mårtensson
Microsoft Regional Director, Azure MVP, CEO Loftysoft
Avirag Jain
Director & CTO R Systems
Mahesh Chand
Founder C# Corner, CEO Mindcracker
Chris Gali
CEO & Co-Founder Graphite
Subinder Khurana
Chief Architect StoryProcess, Founder NASSCOM DeepTech Club
Bryan Rishforth
Investor, Chairman Graphite
Bryn Everson
Director Biz Dev Graphite
Raj Tiwari
Digital Transformation Leader, Futurist and Visionary
Joseph Guadagno
Microsoft MVP, Lead Quicken Loans
Nikita Sachdev
Entrepreneur, Blockchain Enthusiast & Advisor, Social Media Influencer
Doug Wagner
COO & Founder Adapt Technical Group
Ritesh Modi
Architect, Senior Evangelist, Cloud Architect
Crystal Wenrick
Director Communications Mindcracker
Allen O’Neill
Microsoft MVP, Consulting Engineer/Architect
Praveen Kumar
CEO MCN Solutions
Chris Love
Founder Love2Dev, Microsoft MVP, Author
Sanjay Vyas
Microsoft Regional Director, Microsoft MVP, Founder & CEO SkillLabs Technologies
Veena Sarda
Deep Learning Consultant, Author
Sekhar Srinivasan
C# Corner MVP, Microsoft Certified Trainer, Pluralsight Author
Lalit Bansal
Founder & CEO - EIY SYS
Navdeep Garg
CEO Revinfotech
Prakash Tripathi
Tech Manager/Leader, Microsoft MVP, Blogger
Bhavna Jain
Breakthrough Consultant
Naveen Sharma
Enterprise Architect, Leadership Coach, Author
Vidya Vrat Agarwal
Principal Architect, Microsoft MVP, Author
Sheetal Agarwal
Founder Clownselors, Medical Clown, Trainer
Abhishek Kant
Founder GTM Catalyst
Vishnu Saran
Founder & CEO VoiceQube
Sandeep Soni
Founder & CEO Deccansoft, Microsoft Certified Trainer
Parveen Malik
AVP InfoSec & Vulnerability Management, Information Security Expert
Nitin Pandit
Microsoft MVP, Developer Evangelist, Author
Niloshima Srivastava
C# Corner MVP, Tech Architect, Trainer, Blogger
Bala Chirtsabesan
Senior Software Engineer at Microsoft, Author
Manoj Mittal
Sr. Technical Architect, C# Corner MVP, Author
Chandni Di
Co-Founder Voice of Slum
Vithal Wadje
Technical Lead, Microsoft MVP, Author
Shivam Ahuja
Founder SkillCircle, Business Mentor
Chervine Bhiwoo
Solution Architect, Microsoft MVP, Author
Saurabh Jain
Vice President Paytm, Founder Fun2Do Labs, Author
Vinay Solanki
Head IoT at Lenovo, Founder IoT-NCR
Anshu kumari
Founder Blockchainkids, Inventor, Trainer
Amit Singal
CEO Startup Buddy
Dev Pratap
Co-Founder & CEO Voice of Slum
Amey Vartak
Technology Consultant, Full Stack Developer, C# Corner MVP, Author
Viswanatha Swamy
Principal Software Engineer, C# Corner MVP, Author
Sanket Verma
Research Engineer @ Ballistics (Forensics) and Chair, PyData Delhi
Sourabh Somani
Lead Developer, Microsoft MVP, Author
Abhishek Mishra
Software Architect, C# Corner MVP, Author
Siddharth Vaghasia
Technical Consultant, C# Corner MVP, Blogger
Bassam Alugili
Senior Software Specialist, Database Expert
S Ravi Kumar
Solution Architect, C# Corner MVP, Author
Sundaram Subramanian
Full Stack Developer, C# Corner MVP, Speaker
Deepesh Somani
Solution Architect, Microsoft MVP, Author
Debasis Saha
Technical Project Manager, C# Corner MVP, Blogger, Author
Vipul Jain
Software Architect, C# Corner MVP, Author
Akshay Patel
Technical Architect, Microsoft Certified Trainer, C# Corner MVP, Author
Stephen Simon
RPA Developer, Evangelist, Author
Vivek Sharma
Founder Kingster636, AR/VR Specialist
Jeetendra Gund
Technical Lead, C# Corner MVP, Author
Sujal Beniwal
AI Enthusiast, Student
M Viknaraj
Microsoft MVP, Azure Architect, Author
Prasham Sabadra
Software Architect, C# Corner MVP, Trainer, Author
Aakash Maurya
Senior Developer, C# Corner MVP, Speaker
Ankit Sharma
Senior Software Engineer, C# Corner MVP, Author
Mangesh Gaherwar
Team Lead, C# Corner MVP, Author
Viral Jain
Technical Consultant, C# Corner MVP, Author
Bhasker Das
Solution Architect, Evangelist
Manish Dwivedi
Associate Project Manager
Ck Nitin
Programmer, Author
Rohit Gupta
Technical Trainer, Author
Manish Tewatia
Full-stack Marketer, UX Designer
Bhavya Gaur
Technical Illustrator
Rohit Tomar
SEO/SMO Expert
Web Track
Cloud & Data Track
Dev Track
Registration & Breakfast
Future of Desktop Apps with JS (ElectronJs)
Nitin Pandit
Building Serverless Microservices Using Microsoft Azure
Vithal Wadje
Innovating RPA: A Robot for Every Person
Stephen Simon
Managing Cloud Storage Accounts using Logic Apps
Viknaraj Manogararajah
Data visualization using Python
Sekhar Srinivasan
Going Cross platform with AR Foundation
Vivek Sharma
Keynote
Managing your Azure dependencies in ASP.NET Core apps using VS
Bala Chirtsabesan
Securing Applications on Intelligent Azure
Abhishek Mishra
Getting started with Blazor the Framework of Future
S Ravi Kumar
Lunch
Build Progressive Web Apps using Angular 9
Debasis Saha
Build and deploy to any platform using Azure DevOps
Chervine Bhiwoo
Deep Dive in Azure Service Bus
Akshay Patel
Build a Native Mobile Application using React Native and JavaScript
Joseph Guadagno
Making sense of Web Job, Web Job SDK and Functions in Azure
Prakash Tripathi
CloudFront Distribution in AWS
Viral Jain
Tea Break
Introduction to PowerBI
Aakash Maurya
Build Advanced SPFx solutions with React and Graph API
Siddharth Vaghasia
Build Business Intelligence Analyst (BIA) Skills
Sundaram Subramanian
Deep dive of Power Platform – AI BUILDER
Prasham Sabadra
Panel 1
What's new in SharePoint development
Vipul Jain
Build a SSO (Single Sign On) based Native JavaScript application with Microsoft Identity within 10 minutes
Manoj Mittal
Panel 2
Applications and working of AI
Veena Sarda
Deploying serverless API's with .Net core 3.0 on AWS & Azure
Amey Vartak
Panel 3
Blockchain with .NET Core (Ark)
Anshu Kumari
Closing Note & Prize Distribution
Dev Track
Cloud Track
Architecture Track
Emerging Tech Track
Registration & Breakfast
Creating Full-Stack Web Apps Using Server-Side Blazor
Ankit Sharma
Real time face recognition with MS Cognitive Services
Niloshima Srivastava
Building Scalable APIs with GraphQL
Jeetendra Gund
Future of development with AI and Blockchain
Navdeep Garg
Debugging Tips and Tricks with Visual Studio 2019
Joseph Guadagno
Azure Containers
Abhishek Kant
Enterprise Architecture
Naveen Sharma
Bot Framework - learn it fast and look like a boss!
Allen O’Neill
Keynote
.Net Core & C# 8 Performance
David McCarter
Working with Azure kubernetes services
Ritesh Modi
Becoming an Architect
Vidyavrat Agarwal
Why Techies Need to Learn Product Management
Saurabh Jain
Lunch
Build a rules engine in .Net Core
Sanjay Vyas
Building CI and CD Pipeline using Azure DevOps
Sandeep Soni
Entity Framework Core - Tips and Tricks, Performance Optimization, and Tuning
Bassam Alugili
Hacking your way into Data Science
Sanket Verma
Speed up your .Net Core Website
Sourabh Somani
Azure
Magnus Mårtensson
Demystifying Open Distro for Elasticsearch
Suman Debnath
Future of Data
Shivam Ahuja
Tea Break
gRPC with C# and .Net Core
Mangesh Gaherwar
Panel 1
Essentials of Cloud security
Parveen Malik
Power platform and Dynamics 365
Deepesh Somani
Microservices - the gRPC Way
Viswanatha Swamy
Panel 2
Reserved
Reserved
Closing Note & Prize Distribution
Building Resilient .NET Microservices with Polly
Microservices give Australian organisations flexibility to release features independently, scale selected workloads and choose suitable cloud services. They also introduce a network between operations that once ran inside a single process. A payment API can become slow, a stock service can return a temporary error, or an Azure dependency can be unavailable in one region while the rest of the application continues operating.
Polly is a resilience and transient-fault-handling library for .NET. It provides policies that control how an application responds to failures, including retries, timeouts, circuit breakers, fallbacks and isolation. Used carefully, these policies help services remain responsive without hiding serious faults or creating a wave of repeated requests across the system.
Why Resilience Matters in Microservices
A method call inside a monolith usually has predictable process-level behaviour. A microservice call crosses a network, passes through load balancers and authentication layers, and may depend on a database or another external provider. Each boundary adds possible failure modes: connection resets, DNS problems, HTTP 429 responses, slow queries and brief service interruptions.
A useful resilience strategy distinguishes between transient and permanent faults. A short-lived timeout may be worth retrying, while a 400 Bad Request generally requires a code or data correction. Retrying every failure can increase pressure on an already struggling dependency, especially when dozens of application instances make the same decision at the same time.
Australian systems often need to account for geographic distance. An application serving customers in Perth may communicate with resources hosted in the Sydney Azure region, while users in Melbourne or Brisbane experience different network paths and latency. Polly cannot fix poor architecture or an undersized service, but it can make expected network uncertainty manageable.
Retry Policies Without Creating More Failure
A retry policy repeats an operation after a failure, usually with a delay between attempts. It works well for temporary HTTP 408, 429, 502, 503 and 504 responses, provided the request is safe to repeat. Exponential backoff increases the wait after each attempt, reducing the chance that all clients will retry simultaneously.
Jitter adds a small random variation to each delay. Without jitter, thousands of instances can follow the same retry schedule and send another burst at exactly the same moment. This “thundering herd” effect is particularly harmful during a regional incident or after a popular Australian retail website releases a limited product drop.
Retries must respect operation semantics. A GET request is normally easier to repeat than a POST that creates an order, unless the receiving API supports idempotency keys. A practical policy should set a maximum number of attempts, inspect the response status, record the reason for each retry and avoid retrying authentication failures or validation errors.
In Polly, a retry can be composed with a timeout and a circuit breaker. The order matters: a timeout limits how long an individual attempt can run, while the retry policy determines whether another attempt is allowed. The total request budget should include all attempts, so a caller does not wait far longer than the user interface or upstream gateway permits.
Timeouts, Circuit Breakers and Fallbacks
A timeout is one of the most important resilience controls because an unbounded request can consume a thread, socket or connection-pool entry. Every outbound call should have a deliberate limit based on its purpose. A search request may need a shorter budget than a batch operation, while a health check should usually fail quickly.
A circuit breaker stops calls to a dependency after a defined pattern of failures. In the open state, calls fail immediately for a cooling-off period. The breaker then permits limited test calls in a half-open state. If the dependency has recovered, normal traffic resumes; if not, the circuit remains open.
Fallbacks provide a controlled alternative when the preferred operation fails. A product catalogue might return recently cached data, and a notification service might place an event on a durable queue. A fallback should be honest about freshness and availability. Returning stale stock information as if it were current can be more damaging than displaying a temporary error.
Bulkhead isolation limits how many concurrent operations can consume a particular resource. Separate limits for payment, reporting and catalogue calls can prevent a slow reporting provider from exhausting all available worker capacity. This is useful for SaaS platforms serving customers across Australian time zones, where a large batch workload can otherwise compete with daytime transactions.
Choosing Policies for Different Calls
Resilience policies should be designed around the dependency and business operation rather than applied as a universal template. A read-only catalogue request may use a short timeout, a few jittered retries and a circuit breaker. A payment command may use a single carefully bounded attempt, an idempotency key and a reconciliation process rather than automatic repetition.
The following combinations provide a practical starting point. Values must be tested against real latency, provider limits and service-level objectives rather than copied unchanged into production.
| Dependency or operation | Suitable controls | Important caution |
|---|---|---|
| Read-only HTTP query | Timeout, limited retry, circuit breaker | Retry only transient responses; use cached data when appropriate |
| Payment or order submission | Timeout, idempotency key, circuit breaker | Do not blindly repeat a non-idempotent command |
| Rate-limited API | Backoff with jitter, 429 handling | Honour Retry-After and provider quotas |
| Optional recommendation service | Timeout, fallback, bulkhead | Return a useful degraded response |
| Database connection | Timeout, pool limits, selective retry | Avoid retry storms during database pressure |
| Message broker publish | Bounded retry, durable outbox | Prevent duplicate messages and lost events |
In a .NET service, policies can be attached to an HttpClient through IHttpClientFactory. Named or typed clients make it possible to give an inventory provider a different policy from an identity provider. This arrangement also manages handler lifetimes more safely than creating a new HttpClient for every request.
Polly’s classic policy model commonly uses constructs such as WaitAndRetryAsync, CircuitBreakerAsync, TimeoutAsync and FallbackAsync. Newer Polly releases use a resilience pipeline approach, while the underlying engineering principles remain the same. Teams maintaining an older .NET application should check package versions and migration guidance before mixing configuration styles.
Composing Policies in a .NET Service
A policy pipeline should have a clear responsibility at each stage. A typical outbound call might apply a timeout around the attempt, retry selected transient failures with backoff, and use a circuit breaker to stop traffic when repeated attempts fail. The exact ordering should be documented because it changes how many calls are made and how failures are measured.
For example, a retry policy might allow three attempts with delays of roughly 200 milliseconds, 500 milliseconds and one second, plus jitter. A circuit breaker could open after a defined number of failures within a window and remain open for 30 seconds. These figures are illustrative; a high-volume API may need stricter limits, while a batch process could tolerate a longer budget.
Policy registration belongs close to dependency configuration, while business-specific fallback behaviour belongs in the application layer. A service should avoid catching every exception and returning a generic success response. That approach makes monitoring misleading and may cause downstream systems to believe an operation completed when it did not.
Configuration should be externalised so operators can tune limits without rebuilding the service. Australian organisations may run workloads in Azure Australia East or Australia Southeast and maintain separate production and disaster-recovery environments. Timeouts and failure thresholds should be tested in each environment because network distance, provider quotas and traffic patterns differ.
Observability and Operational Safety
A resilience policy is effective only when engineers can see what it is doing. Log the dependency name, operation, attempt number, delay, status code and correlation identifier. Metrics should distinguish original failures from retry attempts, and should record circuit-breaker state changes, timeout counts and fallback usage.
Distributed tracing helps connect a customer request with calls across several services. A trace showing one incoming request followed by four retries reveals a very different problem from a trace containing one failed attempt. OpenTelemetry can provide a consistent approach across .NET services, while dashboards can show dependency latency and error rates by region.
Alerting should focus on sustained customer impact rather than every individual retry. A small number of retries may be normal during network variation. A rising retry rate combined with increased latency, open circuits or fallback responses indicates a dependency problem that needs investigation.
Privacy and data handling also belong in operational design. Under Australia’s Privacy Act 1988 and the Australian Privacy Principles, logs should avoid unnecessary personal information, payment details and authentication tokens. A trace identifier is generally safer than copying a customer’s email address into every log entry. Teams should also understand where telemetry is stored and whether cross-border transfer arrangements meet organisational and regulatory requirements.
Testing Failure Behaviour Before Production
Resilience code should be tested as deliberately as ordinary business logic. Unit tests can verify that a 503 is retried, a 400 is not retried, a breaker opens after the configured threshold and a fallback returns the expected degraded result. Tests should also confirm that cancellation tokens and request deadlines are respected.
Integration tests can use a local stub server to introduce delays, dropped connections, malformed responses and sequences of failures followed by recovery. Injecting a 2.5-second delay into an API call is a simple way to confirm that the timeout behaves as expected. Testing a 429 response verifies that the service respects rate limits rather than increasing traffic.
Load testing is essential because retry behaviour multiplies traffic. If 100 requests fail and each is attempted three times, the dependency may receive up to 300 calls. A chaos test can combine high latency with partial errors to reveal whether connection pools, queues and thread resources remain stable.
Teams should also test graceful recovery. When a circuit closes, the first successful requests should not cause a sudden overload. When a fallback serves cached data, the cache should have a defined age and invalidation policy. These checks matter for services used during Australian peak periods such as end-of-financial-year processing, major sales events and morning commuter traffic.
Building a Sustainable Resilience Strategy
Polly should support a broader reliability practice that includes sensible service boundaries, health checks, capacity planning and clear ownership of dependencies. It cannot compensate for a service that has no database indexes, a gateway with an unsuitable timeout or an API contract that does not define idempotency.
Every policy needs an operational owner and a reason for its settings. Document which errors are retryable, what the maximum end-to-end duration is, how a circuit opens and what users see during fallback. Review these decisions when a provider changes its quotas or when traffic moves between Sydney, Melbourne and other Australian locations.
Resilience also needs to align with business priorities. A banking workflow may prefer a visible failure and later reconciliation over duplicate processing. An online media service may accept slightly stale content to preserve availability. A government or healthcare platform may need additional audit controls, data residency checks and strict handling of sensitive information.
Used with discipline, Polly gives .NET teams a practical vocabulary for handling unreliable dependencies. Retries address brief faults, timeouts enforce boundaries, circuit breakers prevent cascading failure, fallbacks preserve selected user experiences and bulkheads contain resource pressure. The result is a service that fails in a controlled, observable way rather than allowing a small dependency problem to spread throughout the platform.
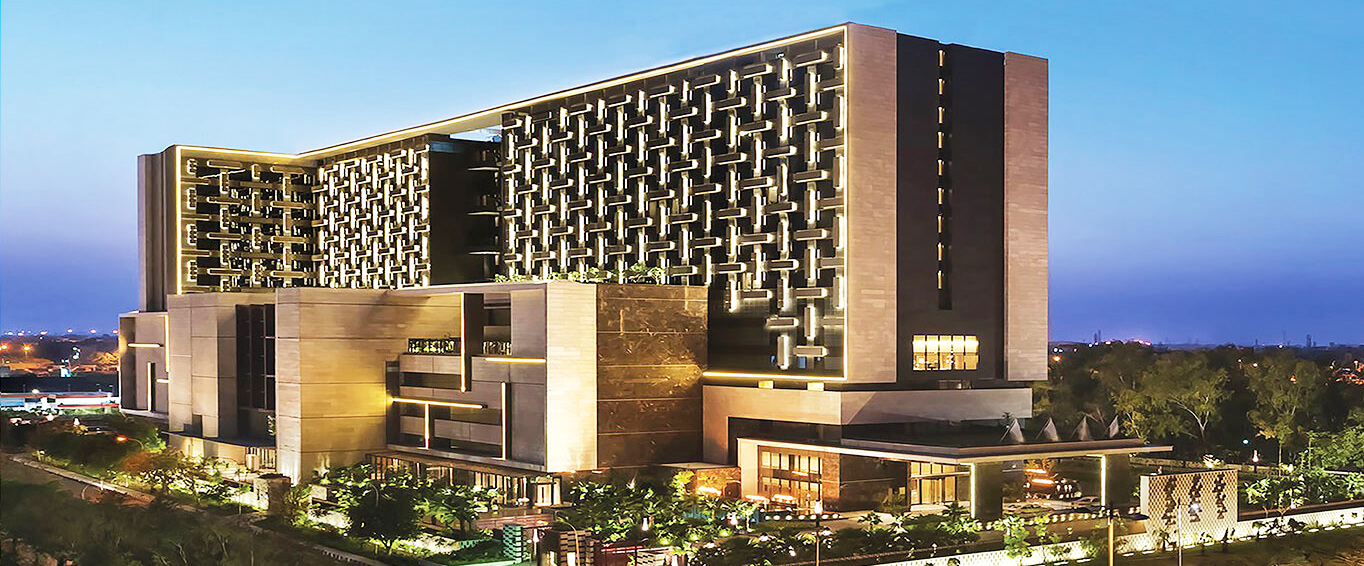
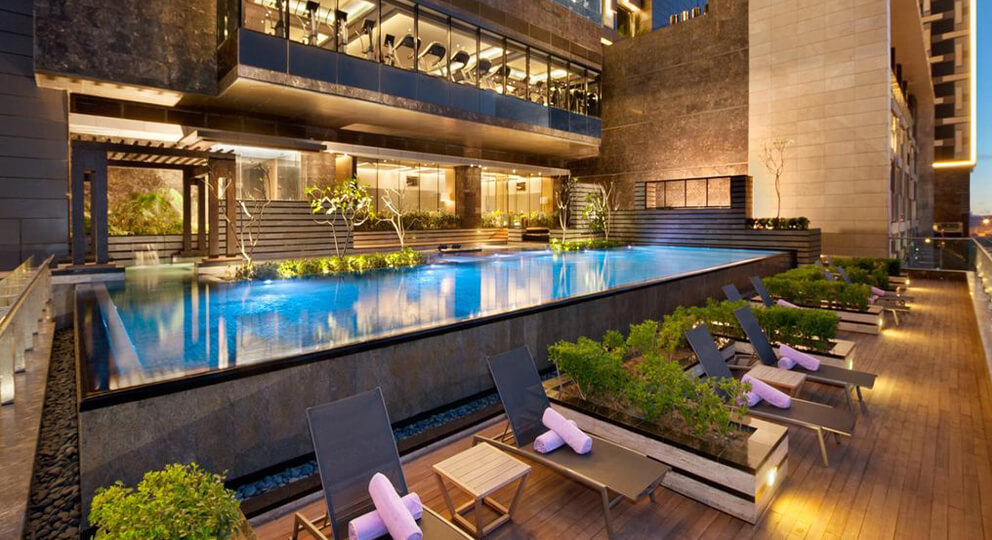
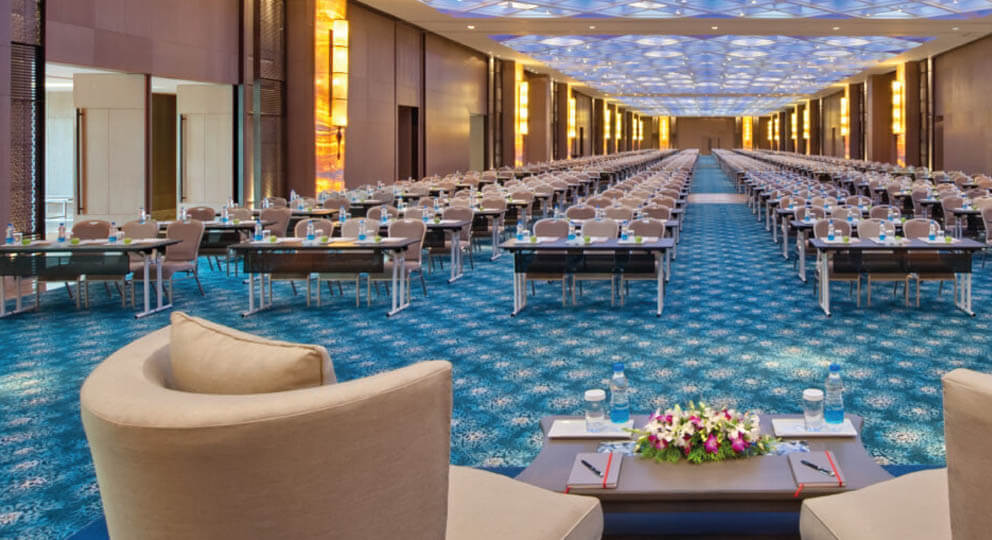
1, CBD, Maharaj Surajmal Road, Near Yamuna Sports Complex, Delhi, 110032
GENERAL QUERIES
Manish Tewatia
manish@csharpcon.com
+91-9718-431-042
TICKET QUERIES
Atul Gupta
conference@csharpcon.com
+91-9910-125-804