Presents
Magnus Mårtensson
Microsoft Regional Director, Azure MVP, CEO Loftysoft
Avirag Jain
Director & CTO R Systems
Mahesh Chand
Founder C# Corner, CEO Mindcracker
Chris Gali
CEO & Co-Founder Graphite
Subinder Khurana
Chief Architect StoryProcess, Founder NASSCOM DeepTech Club
Bryan Rishforth
Investor, Chairman Graphite
Bryn Everson
Director Biz Dev Graphite
Raj Tiwari
Digital Transformation Leader, Futurist and Visionary
Joseph Guadagno
Microsoft MVP, Lead Quicken Loans
Nikita Sachdev
Entrepreneur, Blockchain Enthusiast & Advisor, Social Media Influencer
Doug Wagner
COO & Founder Adapt Technical Group
Ritesh Modi
Architect, Senior Evangelist, Cloud Architect
Crystal Wenrick
Director Communications Mindcracker
Allen O’Neill
Microsoft MVP, Consulting Engineer/Architect
Praveen Kumar
CEO MCN Solutions
Chris Love
Founder Love2Dev, Microsoft MVP, Author
Sanjay Vyas
Microsoft Regional Director, Microsoft MVP, Founder & CEO SkillLabs Technologies
Veena Sarda
Deep Learning Consultant, Author
Sekhar Srinivasan
C# Corner MVP, Microsoft Certified Trainer, Pluralsight Author
Lalit Bansal
Founder & CEO - EIY SYS
Navdeep Garg
CEO Revinfotech
Prakash Tripathi
Tech Manager/Leader, Microsoft MVP, Blogger
Bhavna Jain
Breakthrough Consultant
Naveen Sharma
Enterprise Architect, Leadership Coach, Author
Vidya Vrat Agarwal
Principal Architect, Microsoft MVP, Author
Sheetal Agarwal
Founder Clownselors, Medical Clown, Trainer
Abhishek Kant
Founder GTM Catalyst
Vishnu Saran
Founder & CEO VoiceQube
Sandeep Soni
Founder & CEO Deccansoft, Microsoft Certified Trainer
Parveen Malik
AVP InfoSec & Vulnerability Management, Information Security Expert
Nitin Pandit
Microsoft MVP, Developer Evangelist, Author
Niloshima Srivastava
C# Corner MVP, Tech Architect, Trainer, Blogger
Bala Chirtsabesan
Senior Software Engineer at Microsoft, Author
Manoj Mittal
Sr. Technical Architect, C# Corner MVP, Author
Chandni Di
Co-Founder Voice of Slum
Vithal Wadje
Technical Lead, Microsoft MVP, Author
Shivam Ahuja
Founder SkillCircle, Business Mentor
Chervine Bhiwoo
Solution Architect, Microsoft MVP, Author
Saurabh Jain
Vice President Paytm, Founder Fun2Do Labs, Author
Vinay Solanki
Head IoT at Lenovo, Founder IoT-NCR
Anshu kumari
Founder Blockchainkids, Inventor, Trainer
Amit Singal
CEO Startup Buddy
Dev Pratap
Co-Founder & CEO Voice of Slum
Amey Vartak
Technology Consultant, Full Stack Developer, C# Corner MVP, Author
Viswanatha Swamy
Principal Software Engineer, C# Corner MVP, Author
Sanket Verma
Research Engineer @ Ballistics (Forensics) and Chair, PyData Delhi
Sourabh Somani
Lead Developer, Microsoft MVP, Author
Abhishek Mishra
Software Architect, C# Corner MVP, Author
Siddharth Vaghasia
Technical Consultant, C# Corner MVP, Blogger
Bassam Alugili
Senior Software Specialist, Database Expert
S Ravi Kumar
Solution Architect, C# Corner MVP, Author
Sundaram Subramanian
Full Stack Developer, C# Corner MVP, Speaker
Deepesh Somani
Solution Architect, Microsoft MVP, Author
Debasis Saha
Technical Project Manager, C# Corner MVP, Blogger, Author
Vipul Jain
Software Architect, C# Corner MVP, Author
Akshay Patel
Technical Architect, Microsoft Certified Trainer, C# Corner MVP, Author
Stephen Simon
RPA Developer, Evangelist, Author
Vivek Sharma
Founder Kingster636, AR/VR Specialist
Jeetendra Gund
Technical Lead, C# Corner MVP, Author
Sujal Beniwal
AI Enthusiast, Student
M Viknaraj
Microsoft MVP, Azure Architect, Author
Prasham Sabadra
Software Architect, C# Corner MVP, Trainer, Author
Aakash Maurya
Senior Developer, C# Corner MVP, Speaker
Ankit Sharma
Senior Software Engineer, C# Corner MVP, Author
Mangesh Gaherwar
Team Lead, C# Corner MVP, Author
Viral Jain
Technical Consultant, C# Corner MVP, Author
Bhasker Das
Solution Architect, Evangelist
Manish Dwivedi
Associate Project Manager
Ck Nitin
Programmer, Author
Rohit Gupta
Technical Trainer, Author
Manish Tewatia
Full-stack Marketer, UX Designer
Bhavya Gaur
Technical Illustrator
Rohit Tomar
SEO/SMO Expert
Web Track
Cloud & Data Track
Dev Track
Registration & Breakfast
Future of Desktop Apps with JS (ElectronJs)
Nitin Pandit
Building Serverless Microservices Using Microsoft Azure
Vithal Wadje
Innovating RPA: A Robot for Every Person
Stephen Simon
Managing Cloud Storage Accounts using Logic Apps
Viknaraj Manogararajah
Data visualization using Python
Sekhar Srinivasan
Going Cross platform with AR Foundation
Vivek Sharma
Keynote
Managing your Azure dependencies in ASP.NET Core apps using VS
Bala Chirtsabesan
Securing Applications on Intelligent Azure
Abhishek Mishra
Getting started with Blazor the Framework of Future
S Ravi Kumar
Lunch
Build Progressive Web Apps using Angular 9
Debasis Saha
Build and deploy to any platform using Azure DevOps
Chervine Bhiwoo
Deep Dive in Azure Service Bus
Akshay Patel
Build a Native Mobile Application using React Native and JavaScript
Joseph Guadagno
Making sense of Web Job, Web Job SDK and Functions in Azure
Prakash Tripathi
CloudFront Distribution in AWS
Viral Jain
Tea Break
Introduction to PowerBI
Aakash Maurya
Build Advanced SPFx solutions with React and Graph API
Siddharth Vaghasia
Build Business Intelligence Analyst (BIA) Skills
Sundaram Subramanian
Deep dive of Power Platform – AI BUILDER
Prasham Sabadra
Panel 1
What's new in SharePoint development
Vipul Jain
Build a SSO (Single Sign On) based Native JavaScript application with Microsoft Identity within 10 minutes
Manoj Mittal
Panel 2
Applications and working of AI
Veena Sarda
Deploying serverless API's with .Net core 3.0 on AWS & Azure
Amey Vartak
Panel 3
Blockchain with .NET Core (Ark)
Anshu Kumari
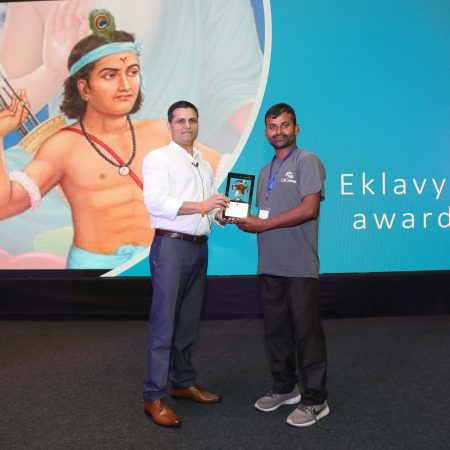
Closing Note & Prize Distribution
Dev Track
Cloud Track
Architecture Track
Emerging Tech Track
Registration & Breakfast
Creating Full-Stack Web Apps Using Server-Side Blazor
Ankit Sharma
Real time face recognition with MS Cognitive Services
Niloshima Srivastava
Building Scalable APIs with GraphQL
Jeetendra Gund
Future of development with AI and Blockchain
Navdeep Garg
Debugging Tips and Tricks with Visual Studio 2019
Joseph Guadagno
Azure Containers
Abhishek Kant
Enterprise Architecture
Naveen Sharma
Bot Framework - learn it fast and look like a boss!
Allen O’Neill
Keynote
.Net Core & C# 8 Performance
David McCarter
Working with Azure kubernetes services
Ritesh Modi
Becoming an Architect
Vidyavrat Agarwal
Why Techies Need to Learn Product Management
Saurabh Jain
Lunch
Build a rules engine in .Net Core
Sanjay Vyas
Building CI and CD Pipeline using Azure DevOps
Sandeep Soni
Entity Framework Core - Tips and Tricks, Performance Optimization, and Tuning
Bassam Alugili
Hacking your way into Data Science
Sanket Verma
Speed up your .Net Core Website
Sourabh Somani
Azure
Magnus Mårtensson
Demystifying Open Distro for Elasticsearch
Suman Debnath
Future of Data
Shivam Ahuja
Tea Break
gRPC with C# and .Net Core
Mangesh Gaherwar
Panel 1
Essentials of Cloud security
Parveen Malik
Power platform and Dynamics 365
Deepesh Somani
Microservices - the gRPC Way
Viswanatha Swamy
Panel 2
Reserved
Reserved
Closing Note & Prize Distribution
Using Azure Monitor Alerts for Proactive .NET Application Monitoring
A .NET application can appear healthy while users experience slow pages, failed API calls, or intermittent sign-in problems. Traditional monitoring often discovers these issues after a support ticket arrives. Azure Monitor changes that operating model by collecting telemetry continuously and turning meaningful signals into alerts, dashboards, and automated responses.
For teams working with ASP.NET Core, Azure App Service, Azure Functions, containers, or virtual machines, the platform provides a shared view of application health. Application Insights captures request performance, dependency calls, exceptions, traces, and availability results, while Log Analytics and Azure Monitor metrics help connect those details with infrastructure behaviour.
That combination is especially useful for Australian organisations operating across Sydney, Melbourne, Brisbane, and Perth. Teams may need to account for Australian Eastern daylight time, local data-residency expectations, and support rosters spread across several states. A carefully designed alerting strategy gives developers and operations staff useful warning before a small fault becomes a production outage.
Building The Monitoring Foundation
The first step is to connect the .NET workload to an Application Insights resource. Modern .NET applications generally use the Azure Monitor OpenTelemetry approach, while older ASP.NET and .NET Framework applications may use the Application Insights SDK. Both approaches collect telemetry that can be explored through the Azure portal, workbooks, and Log Analytics queries.
Useful signals include incoming HTTP requests, response duration, failed requests, outbound SQL or HTTP dependencies, unhandled exceptions, custom events, and distributed traces. A correlation identifier allows an operator to follow a transaction across an API, background worker, database, and third-party service. Without that context, an alert may report a symptom without revealing the component that caused it.
Telemetry should be tagged with information such as application name, environment, region, service version, and business transaction. Avoid placing passwords, access tokens, health information, or unnecessary personal data into logs. This matters for Australian businesses that must consider the Privacy Act, contractual data-handling requirements, and whether telemetry is stored in an approved Azure region.
Selecting Signals That Matter
A useful alert represents a condition that deserves action. Request failure rate is often more valuable than a raw exception count because it reflects the user experience. A small number of handled exceptions may be harmless, whereas a sudden increase in HTTP 500 responses could indicate a deployment, database outage, or configuration problem.
Latency needs similar care. Averages can hide a poor experience for a minority of users, so percentile measurements such as p95 or p99 are usually more informative. An API with a 200-millisecond average may still have a p99 latency of five seconds. Track the endpoints that matter to customers, such as payment, booking, search, or authentication operations.
Availability tests provide an external perspective. A synthetic request from several locations can detect DNS errors, certificate problems, routing failures, and login-page issues that internal dependency checks might miss. For an application serving customers in Sydney and Perth, tests from multiple Australian or nearby locations can reveal regional differences that a single test site cannot.
Creating Metric And Log Alerts
Metric alerts evaluate numerical data at a defined frequency. They work well for request failure percentages, server response time, CPU usage, memory pressure, availability results, and queue depth. A rule can use a static threshold, such as failed requests above five per cent, or dynamic thresholds that learn normal behaviour and flag unusual changes.
Log search alerts use Kusto Query Language, commonly called KQL, to find patterns across Application Insights and Log Analytics. They are appropriate for exceptions containing a particular error code, repeated dependency failures, expired certificates, or a high number of rejected messages. A query can group results by operation name, cloud role, region, or deployment version.
Thresholds should reflect service objectives rather than arbitrary numbers. For example, a background processing service may tolerate a short queue during a lunchtime burst, while an authentication API may require immediate action after a small rise in failures. Establish a baseline during ordinary weekday and weekend traffic before setting production alert rules.
Designing Actionable Notifications
Azure Monitor action groups define what happens after an alert fires. Notifications can be sent by email, SMS, push notification, voice call, webhook, or IT service management integration. An action group can also trigger an Azure Function, Logic App, Automation runbook, or incident-management workflow.
A practical escalation path starts with the team responsible for the service and moves to an on-call engineer when the issue remains unresolved. Microsoft Teams or email may suit informational events, while a severe production outage should reach the person carrying the after-hours roster. Australian organisations should account for AEST and AEDT when documenting schedules, especially when teams work across New South Wales, Victoria, Queensland, and Western Australia.
Every high-priority alert should explain the affected service, observed value, threshold, time window, environment, and a direct link to investigation results. Include a runbook link with checks such as recent deployments, dependency health, failed-operation samples, and rollback guidance. “API errors are high” creates uncertainty; “Checkout API failures reached 8.2 per cent in the last five minutes” gives an operator a starting point.
Reducing Noise And False Alarms
Alert fatigue develops when rules fire too frequently or report conditions that nobody can correct. Avoid creating separate urgent notifications for every symptom of the same outage. A database failure may cause dependency errors, request failures, timeout increases, and exception spikes. These signals can remain visible in dashboards while a single customer-impact alert manages the escalation.
Use evaluation windows, aggregation methods, and suppression rules carefully. A brief CPU spike during a deployment may be harmless, while five consecutive minutes of elevated error rate could indicate a real incident. Dynamic thresholds can help with seasonal traffic, but they should be reviewed because unusual yet legitimate events can otherwise trigger unnecessary warnings.
Test alert rules as part of release engineering. Generate a controlled failure in a non-production environment, confirm that the query finds it, verify the action group, and make sure the alert can be closed or resolved. After an incident, review which notifications helped and which created noise. This operational feedback keeps monitoring aligned with how the service actually runs.
Connecting Alerts With DevOps
Azure Monitor becomes more effective when alert rules are managed as code. Azure Resource Manager templates, Bicep, Terraform, or the Azure SDK can define Application Insights resources, diagnostic settings, action groups, alert criteria, and role assignments. Version-controlled monitoring configuration can then move through development, testing, and production with the application.
Deployment annotations make telemetry easier to interpret. When a new .NET build is released, record its version in Application Insights so operators can compare error rates and latency before and after the change. A spike immediately following a release can support a rollback decision, while a gradual increase may point to a capacity or data-related issue.
The same process supports safer progressive delivery. Deploy to a small percentage of instances, monitor key indicators, and expand only when failure rate and latency remain within agreed limits. Azure DevOps and GitHub Actions can query health signals as part of a pipeline, although automated rollback should be introduced carefully and protected against reacting to short-lived noise.
Applying The Approach To Australian Operations
Regional design is part of application monitoring. An Australian customer base may use services hosted in Australia East or Australia Southeast, yet still depend on global identity providers, payment gateways, content delivery networks, or SaaS platforms. Dependency tracking should identify those external calls and distinguish an internal outage from a provider-side problem.
Australian organisations also operate under practical constraints that vary by sector. A government supplier may need stronger audit evidence and controls aligned with the Essential Eight, while a financial or healthcare business may impose stricter retention and access rules. Azure RBAC, managed identities, private endpoints, diagnostic settings, and carefully limited log access help protect monitoring data without making investigation impossible.
A short “no worries” response is useful only when the service is genuinely healthy; an alert should replace guesswork with evidence. Teams in Melbourne or Sydney may have different business peaks from teams in Perth, and public holidays can alter normal traffic patterns. Build separate baselines for customer-facing APIs, internal tools, batch jobs, and event-driven workloads rather than applying one threshold everywhere.
Comparing Alert Options And Operating Practices
Different alert types solve different monitoring problems. Metric alerts are fast and economical for well-defined numerical signals, while log alerts provide richer investigation logic. Smart detection can surface anomalies automatically, but human review remains important before treating every unusual pattern as an incident.
The following comparison helps map common .NET monitoring needs to an appropriate Azure Monitor capability and response style.
| Monitoring need | Recommended Azure Monitor capability | Useful signal | Typical response |
|---|---|---|---|
| Detect a sudden rise in failed API calls | Metric alert | Failed request percentage | Page the application on-call engineer |
| Find a specific exception or error code | Log search alert | KQL query over exceptions and traces | Notify the owning development team |
| Identify slow customer transactions | Metric or log alert | p95 or p99 request duration | Inspect dependencies and recent releases |
| Confirm public access from outside Azure | Availability test | Synthetic test success rate | Investigate DNS, certificates, routing, or platform health |
| Track unusual behaviour without a fixed limit | Dynamic threshold or smart detection | Anomaly in normal telemetry | Review the pattern before escalation |
| Trigger a controlled operational task | Action group with Logic App or Function | Alert state change | Create a ticket, run a playbook, or scale a service |
A mature setup combines these capabilities with dashboards, workbooks, incident records, and regular alert reviews. The aim is a clear chain from signal to decision: telemetry reveals what changed, an alert identifies what matters, and a runbook guides the next safe action. That pattern helps .NET teams protect user experience while keeping operational effort focused on real service risks.
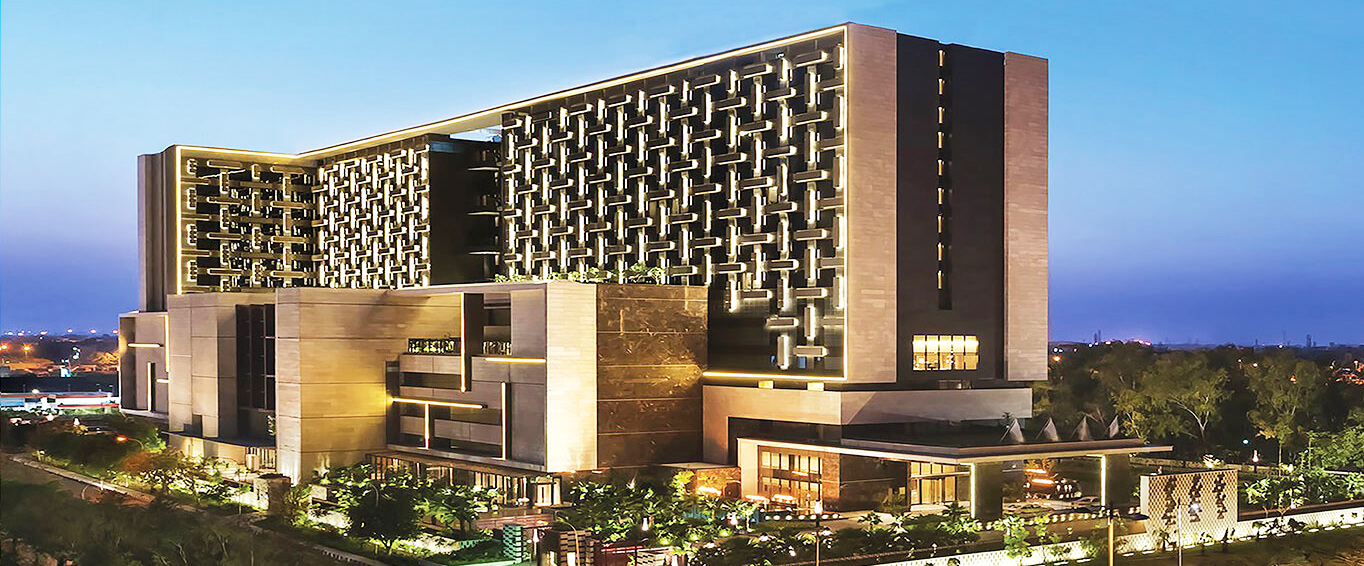
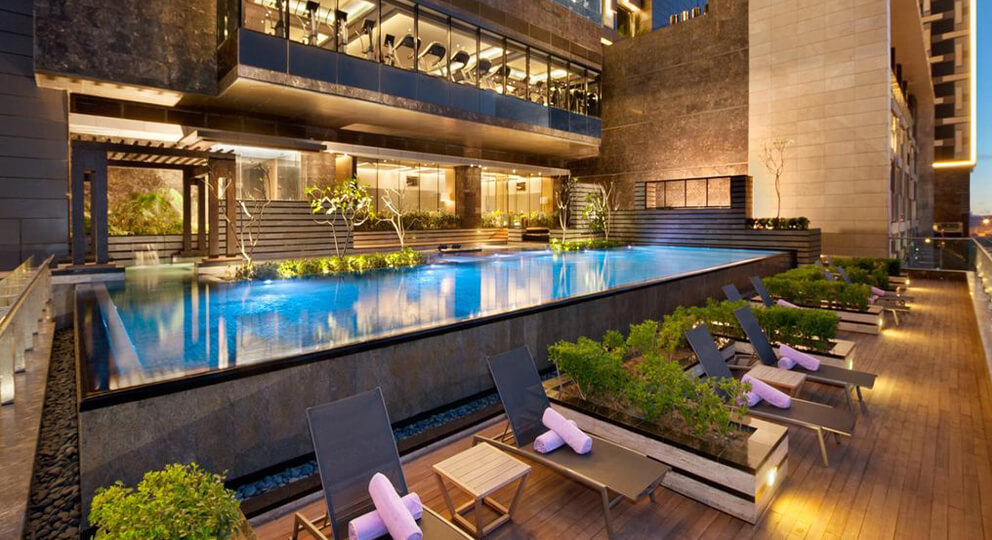
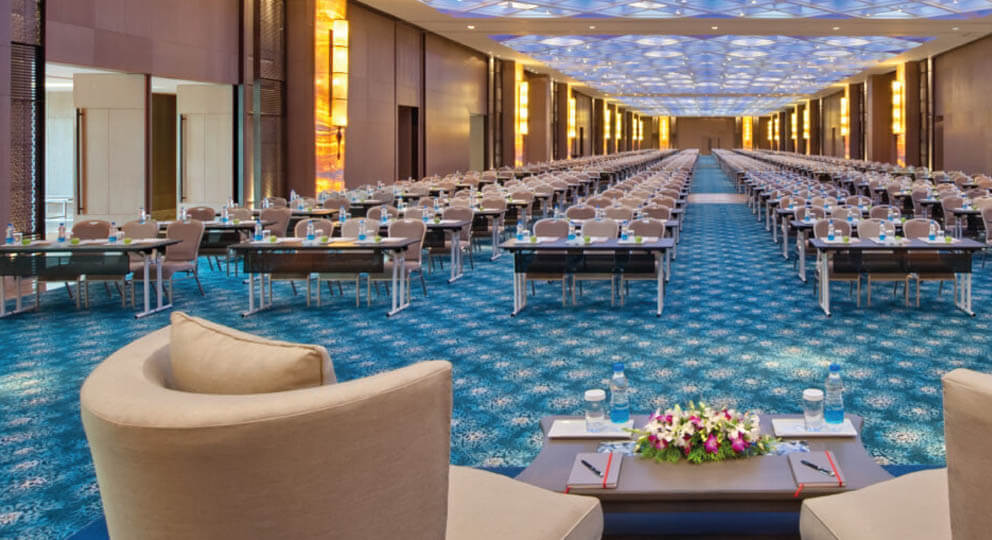
1, CBD, Maharaj Surajmal Road, Near Yamuna Sports Complex, Delhi, 110032
GENERAL QUERIES
Manish Tewatia
manish@csharpcon.com
+91-9718-431-042
TICKET QUERIES
Atul Gupta
conference@csharpcon.com
+91-9910-125-804