Presents
Magnus Mårtensson
Microsoft Regional Director, Azure MVP, CEO Loftysoft
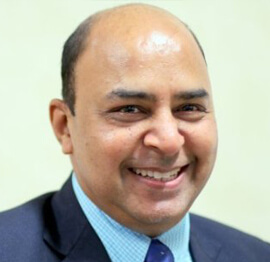
Avirag Jain
Director & CTO R Systems
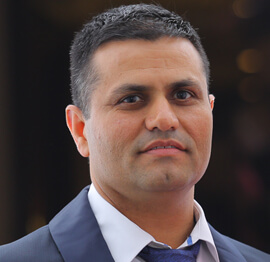
Mahesh Chand
Founder C# Corner, CEO Mindcracker
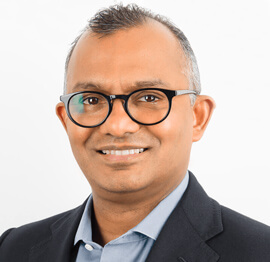
Chris Gali
CEO & Co-Founder Graphite
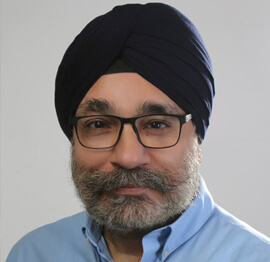
Subinder Khurana
Chief Architect StoryProcess, Founder NASSCOM DeepTech Club
Bryan Rishforth
Investor, Chairman Graphite
Bryn Everson
Director Biz Dev Graphite
Raj Tiwari
Digital Transformation Leader, Futurist and Visionary
Joseph Guadagno
Microsoft MVP, Lead Quicken Loans
Nikita Sachdev
Entrepreneur, Blockchain Enthusiast & Advisor, Social Media Influencer
Doug Wagner
COO & Founder Adapt Technical Group
Ritesh Modi
Architect, Senior Evangelist, Cloud Architect
Crystal Wenrick
Director Communications Mindcracker
Allen O’Neill
Microsoft MVP, Consulting Engineer/Architect
Praveen Kumar
CEO MCN Solutions
Chris Love
Founder Love2Dev, Microsoft MVP, Author
Sanjay Vyas
Microsoft Regional Director, Microsoft MVP, Founder & CEO SkillLabs Technologies
Veena Sarda
Deep Learning Consultant, Author
Sekhar Srinivasan
C# Corner MVP, Microsoft Certified Trainer, Pluralsight Author
Lalit Bansal
Founder & CEO - EIY SYS
Navdeep Garg
CEO Revinfotech
Prakash Tripathi
Tech Manager/Leader, Microsoft MVP, Blogger
Bhavna Jain
Breakthrough Consultant
Naveen Sharma
Enterprise Architect, Leadership Coach, Author
Vidya Vrat Agarwal
Principal Architect, Microsoft MVP, Author
Sheetal Agarwal
Founder Clownselors, Medical Clown, Trainer
Abhishek Kant
Founder GTM Catalyst
Vishnu Saran
Founder & CEO VoiceQube
Sandeep Soni
Founder & CEO Deccansoft, Microsoft Certified Trainer
Parveen Malik
AVP InfoSec & Vulnerability Management, Information Security Expert
Nitin Pandit
Microsoft MVP, Developer Evangelist, Author
Niloshima Srivastava
C# Corner MVP, Tech Architect, Trainer, Blogger
Bala Chirtsabesan
Senior Software Engineer at Microsoft, Author
Manoj Mittal
Sr. Technical Architect, C# Corner MVP, Author
Chandni Di
Co-Founder Voice of Slum
Vithal Wadje
Technical Lead, Microsoft MVP, Author
Shivam Ahuja
Founder SkillCircle, Business Mentor
Chervine Bhiwoo
Solution Architect, Microsoft MVP, Author
Saurabh Jain
Vice President Paytm, Founder Fun2Do Labs, Author
Vinay Solanki
Head IoT at Lenovo, Founder IoT-NCR
Anshu kumari
Founder Blockchainkids, Inventor, Trainer
Amit Singal
CEO Startup Buddy
Dev Pratap
Co-Founder & CEO Voice of Slum
Amey Vartak
Technology Consultant, Full Stack Developer, C# Corner MVP, Author
Viswanatha Swamy
Principal Software Engineer, C# Corner MVP, Author
Sanket Verma
Research Engineer @ Ballistics (Forensics) and Chair, PyData Delhi
Sourabh Somani
Lead Developer, Microsoft MVP, Author
Abhishek Mishra
Software Architect, C# Corner MVP, Author
Siddharth Vaghasia
Technical Consultant, C# Corner MVP, Blogger
Bassam Alugili
Senior Software Specialist, Database Expert
S Ravi Kumar
Solution Architect, C# Corner MVP, Author
Sundaram Subramanian
Full Stack Developer, C# Corner MVP, Speaker
Deepesh Somani
Solution Architect, Microsoft MVP, Author
Debasis Saha
Technical Project Manager, C# Corner MVP, Blogger, Author
Vipul Jain
Software Architect, C# Corner MVP, Author
Akshay Patel
Technical Architect, Microsoft Certified Trainer, C# Corner MVP, Author
Stephen Simon
RPA Developer, Evangelist, Author
Vivek Sharma
Founder Kingster636, AR/VR Specialist
Jeetendra Gund
Technical Lead, C# Corner MVP, Author
Sujal Beniwal
AI Enthusiast, Student
M Viknaraj
Microsoft MVP, Azure Architect, Author
Prasham Sabadra
Software Architect, C# Corner MVP, Trainer, Author
Aakash Maurya
Senior Developer, C# Corner MVP, Speaker
Ankit Sharma
Senior Software Engineer, C# Corner MVP, Author
Mangesh Gaherwar
Team Lead, C# Corner MVP, Author
Viral Jain
Technical Consultant, C# Corner MVP, Author
Bhasker Das
Solution Architect, Evangelist
Manish Dwivedi
Associate Project Manager
Ck Nitin
Programmer, Author
Rohit Gupta
Technical Trainer, Author
Manish Tewatia
Full-stack Marketer, UX Designer
Bhavya Gaur
Technical Illustrator
Rohit Tomar
SEO/SMO Expert
Web Track
Cloud & Data Track
Dev Track
Registration & Breakfast
Future of Desktop Apps with JS (ElectronJs)
Nitin Pandit
Building Serverless Microservices Using Microsoft Azure
Vithal Wadje
Innovating RPA: A Robot for Every Person
Stephen Simon
Managing Cloud Storage Accounts using Logic Apps
Viknaraj Manogararajah
Data visualization using Python
Sekhar Srinivasan
Going Cross platform with AR Foundation
Vivek Sharma
Keynote
Managing your Azure dependencies in ASP.NET Core apps using VS
Bala Chirtsabesan
Securing Applications on Intelligent Azure
Abhishek Mishra
Getting started with Blazor the Framework of Future
S Ravi Kumar
Lunch
Build Progressive Web Apps using Angular 9
Debasis Saha
Build and deploy to any platform using Azure DevOps
Chervine Bhiwoo
Deep Dive in Azure Service Bus
Akshay Patel
Build a Native Mobile Application using React Native and JavaScript
Joseph Guadagno
Making sense of Web Job, Web Job SDK and Functions in Azure
Prakash Tripathi
CloudFront Distribution in AWS
Viral Jain
Tea Break
Introduction to PowerBI
Aakash Maurya
Build Advanced SPFx solutions with React and Graph API
Siddharth Vaghasia
Build Business Intelligence Analyst (BIA) Skills
Sundaram Subramanian
Deep dive of Power Platform – AI BUILDER
Prasham Sabadra
Panel 1
What's new in SharePoint development
Vipul Jain
Build a SSO (Single Sign On) based Native JavaScript application with Microsoft Identity within 10 minutes
Manoj Mittal
Panel 2
Applications and working of AI
Veena Sarda
Deploying serverless API's with .Net core 3.0 on AWS & Azure
Amey Vartak
Panel 3
Blockchain with .NET Core (Ark)
Anshu Kumari
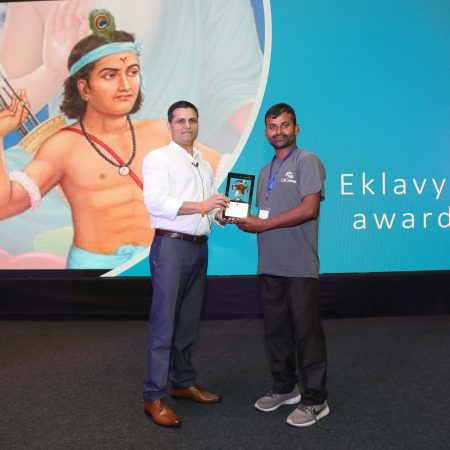
Closing Note & Prize Distribution
Dev Track
Cloud Track
Architecture Track
Emerging Tech Track
Registration & Breakfast
Creating Full-Stack Web Apps Using Server-Side Blazor
Ankit Sharma
Real time face recognition with MS Cognitive Services
Niloshima Srivastava
Building Scalable APIs with GraphQL
Jeetendra Gund
Future of development with AI and Blockchain
Navdeep Garg
Debugging Tips and Tricks with Visual Studio 2019
Joseph Guadagno
Azure Containers
Abhishek Kant
Enterprise Architecture
Naveen Sharma
Bot Framework - learn it fast and look like a boss!
Allen O’Neill
Keynote
.Net Core & C# 8 Performance
David McCarter
Working with Azure kubernetes services
Ritesh Modi
Becoming an Architect
Vidyavrat Agarwal
Why Techies Need to Learn Product Management
Saurabh Jain
Lunch
Build a rules engine in .Net Core
Sanjay Vyas
Building CI and CD Pipeline using Azure DevOps
Sandeep Soni
Entity Framework Core - Tips and Tricks, Performance Optimization, and Tuning
Bassam Alugili
Hacking your way into Data Science
Sanket Verma
Speed up your .Net Core Website
Sourabh Somani
Azure
Magnus Mårtensson
Demystifying Open Distro for Elasticsearch
Suman Debnath
Future of Data
Shivam Ahuja
Tea Break
gRPC with C# and .Net Core
Mangesh Gaherwar
Panel 1
Essentials of Cloud security
Parveen Malik
Power platform and Dynamics 365
Deepesh Somani
Microservices - the gRPC Way
Viswanatha Swamy
Panel 2
Reserved
Reserved
Closing Note & Prize Distribution
Building a Serverless Data Ingestion Pipeline with Azure Functions
Modern applications produce data continuously through web forms, mobile clients, connected devices, business systems, and third-party APIs. Moving that information into reliable storage requires more than a function that accepts a request. The pipeline must absorb traffic spikes, validate untrusted input, recover from temporary failures, and preserve a useful record of what happened.
Azure Functions provides an effective execution layer for this kind of workload. It runs code in response to events and removes much of the infrastructure management associated with continuously running services. When combined with Azure Event Hubs, Blob Storage, Service Bus, Cosmos DB, or Azure Data Lake Storage, it can form a flexible serverless data ingestion architecture.
The design also fits naturally within the broader Microsoft cloud ecosystem explored through conference sessions, where developers examine Azure, data engineering, DevOps, artificial intelligence, and related technologies. The central engineering task is choosing the right trigger, processing boundary, storage model, and operational safeguards.
Define The Ingestion Flow
A useful ingestion pipeline starts with a clear path from producer to destination. A client may send JSON through an HTTP endpoint, a device may publish telemetry to Event Hubs, or an application may place files in Blob Storage. Azure Functions can react to each source through an HTTP trigger, Event Hubs trigger, Blob trigger, or Service Bus trigger.
The first function should usually perform lightweight work: authenticate the caller, check the message shape, attach metadata, and place the event on a durable messaging service. Sending every operation directly to a database inside the initial request creates tight coupling and makes the endpoint vulnerable to slow downstream dependencies.
A queue or event stream creates separation between receiving data and processing it. The ingestion endpoint can acknowledge accepted work quickly, while a second function consumes messages at its own pace. This approach supports independent scaling and makes it easier to retry failed operations without asking the original producer to resend the entire request.
For high-volume telemetry, Event Hubs is designed for streaming events and partitioned consumption. For business commands that need explicit completion, dead-letter handling, and controlled delivery, Service Bus is often a better fit. Blob Storage is well suited to large files and replayable raw data, especially when the source sends periodic exports.
Choose A Durable Data Path
A production pipeline normally benefits from a raw landing zone. The original payload can be written to Blob Storage or Azure Data Lake Storage before extensive transformation. Keeping this immutable or minimally changed copy helps with auditing, replay, troubleshooting, and future analytics requirements.
The raw record should carry useful envelope data, such as ingestion time, source system, event identifier, schema version, correlation identifier, and processing status. This metadata allows engineers to distinguish a malformed source message from a temporary infrastructure failure. It also makes historical reprocessing more controlled.
A downstream Azure Function can normalize the event and write it to an operational store. Cosmos DB is appropriate when applications need flexible JSON documents and low-latency access. Azure SQL Database is a stronger choice for relational constraints, joins, and established transactional models. For analytical workloads, transformed data may be placed in Data Lake Storage and queried through services such as Synapse or serverless SQL.
Storage decisions should reflect access patterns rather than familiarity. A pipeline that receives millions of events but serves only aggregated reports does not need every raw event in a transactional database. Conversely, an application that immediately displays the latest customer state may need a carefully indexed operational projection alongside the historical data lake.
Design Functions Around Events
A serverless function should have a focused responsibility and a predictable execution time. One function might validate and enqueue data, another might enrich it with reference information, and a third might persist the final document. Smaller responsibilities make deployments, tests, permissions, and failure analysis easier to manage.
Azure Functions supports bindings that simplify connections to queues, blobs, Event Hubs, and databases. Bindings can reduce boilerplate, but developers should still understand what happens during retries, partial failures, serialization errors, and host restarts. A convenient binding does not automatically make a write idempotent or transactional.
Idempotency is essential because message delivery can occur more than once. Each event should have a stable identifier, and the destination should be able to recognize an already-processed message. This may involve a unique key in Cosmos DB, a deduplication record, a database constraint, or a state transition that safely ignores duplicates.
Long-running orchestration requires a different design. Durable Functions can coordinate multi-step workflows, timers, checkpoints, and compensating actions. It is useful for processes such as waiting for several files, calling multiple services in sequence, or polling an external system, while ordinary event-triggered functions are usually better for short independent transformations.
Compare Trigger And Storage Choices
The most suitable Azure service depends on traffic shape, message guarantees, payload size, and how the data will be consumed. A small internal application may work well with an HTTP-triggered function and a queue. A global telemetry platform may require partitioned streaming, consumer groups, and a separate analytical storage layer.
| Pipeline concern | Suitable Azure option | Strength | Important consideration |
|---|---|---|---|
| Synchronous event submission | HTTP-triggered Azure Function | Simple integration with web and mobile clients | Protect the endpoint and avoid lengthy processing |
| High-volume telemetry | Azure Event Hubs with a Function trigger | Partitioned streaming and scalable consumption | Plan partitions, offsets, and consumer groups |
| Reliable business messages | Azure Service Bus with a Function trigger | Delivery controls, retries, and dead-letter queues | Set lock duration and concurrency carefully |
| Large file ingestion | Blob Storage with a Blob trigger | Cost-effective landing zone for files | Handle partial uploads and duplicate notifications |
| Flexible operational records | Azure Cosmos DB | Fast JSON document access and elastic scale | Select a partition key that distributes load |
| Historical analytics | Azure Data Lake Storage | Durable, economical storage for raw and curated data | Define file formats, folders, and lifecycle rules |
These services can be combined rather than treated as competing alternatives. For example, an HTTP function can place commands on Service Bus, while a separate Event Hubs path handles device telemetry. Both paths may land raw records in Data Lake Storage before writing curated data to different analytical or operational destinations.
Consumption plans and Premium plans also affect runtime behavior. Consumption can be attractive for intermittent workloads because billing follows execution, while Premium provides prewarmed instances, longer-running capacity, and stronger control over scaling. The correct plan depends on latency requirements, networking needs, workload consistency, and execution duration.
Make Reliability Explicit
Retries should be deliberate rather than unlimited. A transient database timeout may deserve another attempt, while a schema validation failure will continue to fail until the payload changes. Configure retry policies for temporary conditions and route permanently invalid messages to a dead-letter queue or quarantine location.
Poison messages require visibility. A failed event should retain its identifier, error details, source, and retry history without exposing secrets or unnecessary personal data. Operators need a safe way to inspect, correct, and replay the message. A replay process should preserve the original event identity while recording the new processing attempt.
Scaling introduces its own risks. If a function consumes messages faster than a database can accept them, downstream throttling may increase failures and produce a growing backlog. Limit concurrency where necessary, monitor queue age, and use batching only when the target system benefits from it. Backpressure is a design feature, not an inconvenience.
Observability should cover the entire event path. Application Insights can collect traces, exceptions, dependency calls, and performance metrics. Correlation IDs should travel from the producer through each function and storage operation. Useful alerts include rising dead-letter counts, increasing queue latency, repeated function failures, database throttling, and unexpected drops in event volume.
Secure The Serverless Boundary
Authentication and authorization belong at the edge of the pipeline. An HTTP-triggered function can use Microsoft Entra ID, managed identities, function keys where appropriate, or an API gateway that applies stronger policy. Public endpoints should enforce input limits, rate controls, and content validation before accepting work.
Managed identities reduce the need to store credentials in application settings. A function can receive permission to write to Storage, read from Key Vault, or access a database through Azure role assignments. Permissions should be scoped to the specific resource and operation instead of granting broad subscription-level access.
Network controls may be necessary for sensitive workloads. Private endpoints, virtual network integration, firewall rules, and restricted storage accounts can keep traffic away from the public internet. Secrets, certificates, and connection strings should be held in Key Vault, with access audited and rotated according to organizational policy.
Data governance begins during ingestion. Classify personal or regulated information, encrypt data in transit and at rest, define retention periods, and avoid placing sensitive values in logs. A raw landing zone is valuable for replay, but it should not become an uncontrolled permanent archive.
Operate And Improve The Pipeline
Testing should cover individual functions, trigger behavior, serialization, retry logic, and destination failures. Integration tests can use disposable Azure resources or isolated environments to verify the complete event path. Load testing is especially important because serverless systems may scale quickly enough to expose database limits that are invisible in local development.
Infrastructure as code makes environments repeatable. Bicep, ARM templates, or Terraform can define the Function App, storage accounts, queues, access roles, monitoring, and networking. Deployment pipelines should promote the same artifact through development, test, and production while keeping environment-specific settings outside the codebase.
Schema evolution deserves a versioning strategy. Producers and consumers should tolerate compatible additions where possible, and breaking changes should use an explicit version or parallel route. A schema registry, documented contract, or validation library can prevent silent corruption when multiple teams publish events.
Operational dashboards should tell a story rather than display isolated metrics. Track accepted events, successfully processed events, processing latency, retry volume, dead letters, storage failures, and backlog age. Together, these indicators show whether the pipeline is healthy, delayed, losing data, or overwhelming a dependency.
Practical Design Rules
- Assign every event a stable identifier and enforce duplicate-safe writes at the destination.
- Keep the initial trigger fast by moving expensive work to a durable queue or event stream.
- Store an auditable raw copy when replay, compliance, or future analytics is important.
- Separate transient failures from invalid payloads and route each category appropriately.
- Monitor backlog age and downstream throttling, not just function execution counts.
A serverless ingestion solution succeeds when its boundaries are clear: producers submit events, triggers accept them, durable messaging absorbs variation, functions perform focused transformations, and storage preserves the right form of data for its consumers. Azure Functions supplies the execution model, but reliability comes from the surrounding choices involving identity, schema, retries, partitioning, and observability.
Start with a small end-to-end path, measure its behavior under realistic load, and then expand toward enrichment, analytics, and automated replay. Developers can also explore the wider Azure and cloud engineering material available through the conference platform before applying these patterns to their own data workloads.
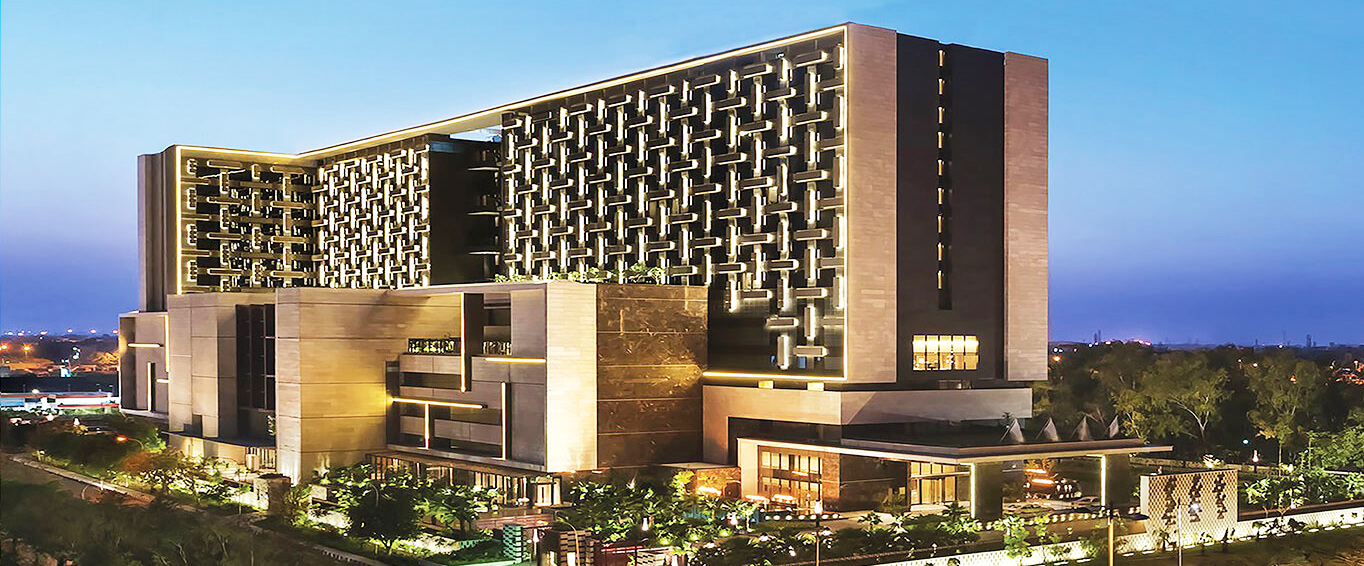
1, CBD, Maharaj Surajmal Road, Near Yamuna Sports Complex, Delhi, 110032
GENERAL QUERIES
Manish Tewatia
manish@csharpcon.com
+91-9718-431-042
TICKET QUERIES
Atul Gupta
conference@csharpcon.com
+91-9910-125-804