Presents
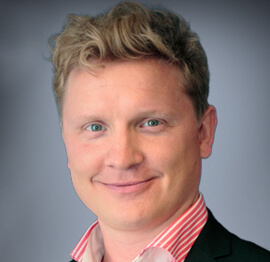
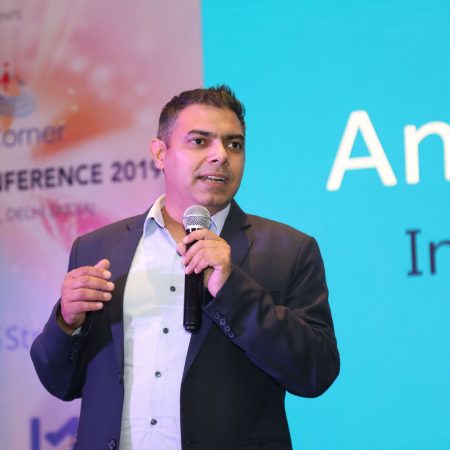
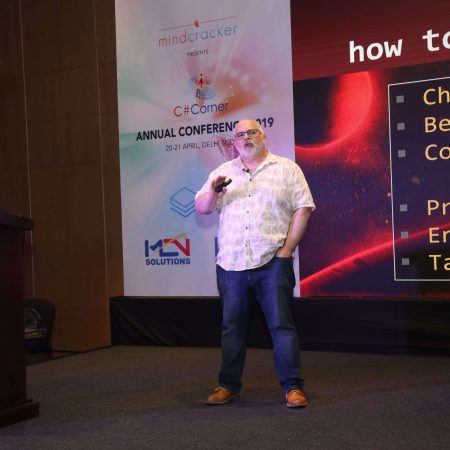
Magnus Mårtensson
Microsoft Regional Director, Azure MVP, CEO Loftysoft
Avirag Jain
Director & CTO R Systems
Mahesh Chand
Founder C# Corner, CEO Mindcracker
Chris Gali
CEO & Co-Founder Graphite
Subinder Khurana
Chief Architect StoryProcess, Founder NASSCOM DeepTech Club
Bryan Rishforth
Investor, Chairman Graphite
Bryn Everson
Director Biz Dev Graphite
Raj Tiwari
Digital Transformation Leader, Futurist and Visionary
Joseph Guadagno
Microsoft MVP, Lead Quicken Loans
Nikita Sachdev
Entrepreneur, Blockchain Enthusiast & Advisor, Social Media Influencer
Doug Wagner
COO & Founder Adapt Technical Group
Ritesh Modi
Architect, Senior Evangelist, Cloud Architect
Crystal Wenrick
Director Communications Mindcracker
Allen O’Neill
Microsoft MVP, Consulting Engineer/Architect
Praveen Kumar
CEO MCN Solutions
Chris Love
Founder Love2Dev, Microsoft MVP, Author
Sanjay Vyas
Microsoft Regional Director, Microsoft MVP, Founder & CEO SkillLabs Technologies
Veena Sarda
Deep Learning Consultant, Author
Sekhar Srinivasan
C# Corner MVP, Microsoft Certified Trainer, Pluralsight Author
Lalit Bansal
Founder & CEO - EIY SYS
Navdeep Garg
CEO Revinfotech
Prakash Tripathi
Tech Manager/Leader, Microsoft MVP, Blogger
Bhavna Jain
Breakthrough Consultant
Naveen Sharma
Enterprise Architect, Leadership Coach, Author
Vidya Vrat Agarwal
Principal Architect, Microsoft MVP, Author
Sheetal Agarwal
Founder Clownselors, Medical Clown, Trainer
Abhishek Kant
Founder GTM Catalyst
Vishnu Saran
Founder & CEO VoiceQube
Sandeep Soni
Founder & CEO Deccansoft, Microsoft Certified Trainer
Parveen Malik
AVP InfoSec & Vulnerability Management, Information Security Expert
Nitin Pandit
Microsoft MVP, Developer Evangelist, Author
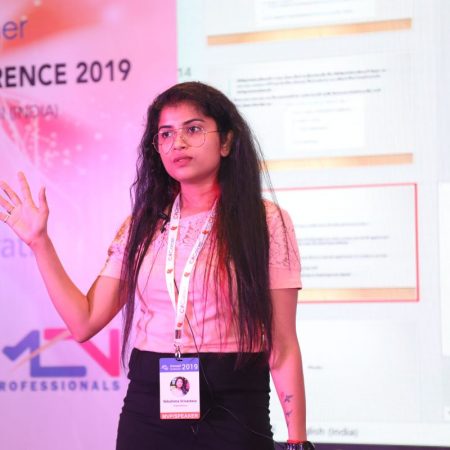
Niloshima Srivastava
C# Corner MVP, Tech Architect, Trainer, Blogger
Bala Chirtsabesan
Senior Software Engineer at Microsoft, Author
Manoj Mittal
Sr. Technical Architect, C# Corner MVP, Author
Chandni Di
Co-Founder Voice of Slum
Vithal Wadje
Technical Lead, Microsoft MVP, Author
Shivam Ahuja
Founder SkillCircle, Business Mentor
Chervine Bhiwoo
Solution Architect, Microsoft MVP, Author
Saurabh Jain
Vice President Paytm, Founder Fun2Do Labs, Author
Vinay Solanki
Head IoT at Lenovo, Founder IoT-NCR
Anshu kumari
Founder Blockchainkids, Inventor, Trainer
Amit Singal
CEO Startup Buddy
Dev Pratap
Co-Founder & CEO Voice of Slum
Amey Vartak
Technology Consultant, Full Stack Developer, C# Corner MVP, Author
Viswanatha Swamy
Principal Software Engineer, C# Corner MVP, Author
Sanket Verma
Research Engineer @ Ballistics (Forensics) and Chair, PyData Delhi
Sourabh Somani
Lead Developer, Microsoft MVP, Author
Abhishek Mishra
Software Architect, C# Corner MVP, Author
Siddharth Vaghasia
Technical Consultant, C# Corner MVP, Blogger
Bassam Alugili
Senior Software Specialist, Database Expert
S Ravi Kumar
Solution Architect, C# Corner MVP, Author
Sundaram Subramanian
Full Stack Developer, C# Corner MVP, Speaker
Deepesh Somani
Solution Architect, Microsoft MVP, Author
Debasis Saha
Technical Project Manager, C# Corner MVP, Blogger, Author
Vipul Jain
Software Architect, C# Corner MVP, Author
Akshay Patel
Technical Architect, Microsoft Certified Trainer, C# Corner MVP, Author
Stephen Simon
RPA Developer, Evangelist, Author
Vivek Sharma
Founder Kingster636, AR/VR Specialist
Jeetendra Gund
Technical Lead, C# Corner MVP, Author
Sujal Beniwal
AI Enthusiast, Student
M Viknaraj
Microsoft MVP, Azure Architect, Author
Prasham Sabadra
Software Architect, C# Corner MVP, Trainer, Author
Aakash Maurya
Senior Developer, C# Corner MVP, Speaker
Ankit Sharma
Senior Software Engineer, C# Corner MVP, Author
Mangesh Gaherwar
Team Lead, C# Corner MVP, Author
Viral Jain
Technical Consultant, C# Corner MVP, Author
Bhasker Das
Solution Architect, Evangelist
Manish Dwivedi
Associate Project Manager
Ck Nitin
Programmer, Author
Rohit Gupta
Technical Trainer, Author
Manish Tewatia
Full-stack Marketer, UX Designer
Bhavya Gaur
Technical Illustrator
Rohit Tomar
SEO/SMO Expert
Web Track
Cloud & Data Track
Dev Track
Registration & Breakfast
Future of Desktop Apps with JS (ElectronJs)
Nitin Pandit
Building Serverless Microservices Using Microsoft Azure
Vithal Wadje
Innovating RPA: A Robot for Every Person
Stephen Simon
Managing Cloud Storage Accounts using Logic Apps
Viknaraj Manogararajah
Data visualization using Python
Sekhar Srinivasan
Going Cross platform with AR Foundation
Vivek Sharma
Keynote
Managing your Azure dependencies in ASP.NET Core apps using VS
Bala Chirtsabesan
Securing Applications on Intelligent Azure
Abhishek Mishra
Getting started with Blazor the Framework of Future
S Ravi Kumar
Lunch
Build Progressive Web Apps using Angular 9
Debasis Saha
Build and deploy to any platform using Azure DevOps
Chervine Bhiwoo
Deep Dive in Azure Service Bus
Akshay Patel
Build a Native Mobile Application using React Native and JavaScript
Joseph Guadagno
Making sense of Web Job, Web Job SDK and Functions in Azure
Prakash Tripathi
CloudFront Distribution in AWS
Viral Jain
Tea Break
Introduction to PowerBI
Aakash Maurya
Build Advanced SPFx solutions with React and Graph API
Siddharth Vaghasia
Build Business Intelligence Analyst (BIA) Skills
Sundaram Subramanian
Deep dive of Power Platform – AI BUILDER
Prasham Sabadra
Panel 1
What's new in SharePoint development
Vipul Jain
Build a SSO (Single Sign On) based Native JavaScript application with Microsoft Identity within 10 minutes
Manoj Mittal
Panel 2
Applications and working of AI
Veena Sarda
Deploying serverless API's with .Net core 3.0 on AWS & Azure
Amey Vartak
Panel 3
Blockchain with .NET Core (Ark)
Anshu Kumari
Closing Note & Prize Distribution
Dev Track
Cloud Track
Architecture Track
Emerging Tech Track
Registration & Breakfast
Creating Full-Stack Web Apps Using Server-Side Blazor
Ankit Sharma
Real time face recognition with MS Cognitive Services
Niloshima Srivastava
Building Scalable APIs with GraphQL
Jeetendra Gund
Future of development with AI and Blockchain
Navdeep Garg
Debugging Tips and Tricks with Visual Studio 2019
Joseph Guadagno
Azure Containers
Abhishek Kant
Enterprise Architecture
Naveen Sharma
Bot Framework - learn it fast and look like a boss!
Allen O’Neill
Keynote
.Net Core & C# 8 Performance
David McCarter
Working with Azure kubernetes services
Ritesh Modi
Becoming an Architect
Vidyavrat Agarwal
Why Techies Need to Learn Product Management
Saurabh Jain
Lunch
Build a rules engine in .Net Core
Sanjay Vyas
Building CI and CD Pipeline using Azure DevOps
Sandeep Soni
Entity Framework Core - Tips and Tricks, Performance Optimization, and Tuning
Bassam Alugili
Hacking your way into Data Science
Sanket Verma
Speed up your .Net Core Website
Sourabh Somani
Azure
Magnus Mårtensson
Demystifying Open Distro for Elasticsearch
Suman Debnath
Future of Data
Shivam Ahuja
Tea Break
gRPC with C# and .Net Core
Mangesh Gaherwar
Panel 1
Essentials of Cloud security
Parveen Malik
Power platform and Dynamics 365
Deepesh Somani
Microservices - the gRPC Way
Viswanatha Swamy
Panel 2
Reserved
Reserved
Closing Note & Prize Distribution
Building a recommendation engine with Azure Machine Learning and C#
Recommendation systems help applications present relevant products, articles, videos, courses, or services to each user. Instead of treating every visitor identically, a recommendation engine learns from behavior and identifies patterns that can guide the next useful action. For software teams, this can improve discovery, engagement, and customer retention without requiring every item to be manually categorized.
A practical solution combines several disciplines: data preparation, machine learning, cloud infrastructure, application development, and monitoring. Azure Machine Learning provides the managed environment for training and deploying models, while C# supplies a strong foundation for integrating predictions into web, desktop, or service-based applications.
The same ideas apply to a technical event platform. A conference website could recommend sessions based on a visitor’s selected interests, previously viewed speakers, preferred technology areas, or attendance history. Developers exploring the wider ecosystem can also find related material through the conference learning hub, where topics such as Azure, AI, cloud computing, and C# are brought together.
Define the recommendation problem
The first decision is to determine what the system should recommend and what action counts as success. A retail engine may suggest products, while a learning platform may suggest sessions or documentation. The target could be a click, registration, purchase, completion, rating, or a combination of these events. A clearly defined objective prevents the model from optimizing an activity that has little business value.
Recommendation engines generally use collaborative filtering, content-based filtering, or a hybrid of both. Collaborative filtering finds relationships between users and items by studying interactions. Content-based filtering compares item attributes with a user’s known preferences. A hybrid approach combines behavioral signals with metadata, which is especially useful when the catalog changes frequently or new items have limited interaction history.
Implicit feedback is often more plentiful than explicit ratings. Page views, search queries, bookmarks, dwell time, registrations, and completed sessions can all provide evidence of interest. These signals should be weighted carefully. A completed registration is usually stronger than a brief page view, while a repeated dismissal may indicate negative preference. Recording the source and strength of each event gives the training process more useful context.
Prepare reliable training data
A recommendation model is only as dependable as the data pipeline supporting it. Begin with a consistent interaction record containing fields such as user identifier, item identifier, event type, timestamp, device context, and optional demographic or organizational attributes. Item records should include descriptive information such as title, category, language, author, technology tags, price, and publication status.
Data cleaning must address duplicate events, missing identifiers, bot traffic, abandoned sessions, and changes to item availability. User identifiers should be pseudonymized where possible, and personally identifiable information should not be included unless it is required for a documented purpose. Access controls, retention policies, and encryption are important parts of a production machine learning system, rather than tasks reserved for a later phase.
Time is a critical feature in recommendation data. A random train-test split can allow future behavior to influence the past, creating an unrealistically high evaluation score. A chronological split is safer: older interactions train the model, a later period validates it, and the most recent period tests it. This setup better reflects how the engine will operate after deployment.
Build the Azure Machine Learning workflow
Azure Machine Learning can organize the lifecycle from dataset registration through model deployment. Data may arrive through Azure Data Lake Storage, Blob Storage, SQL databases, or event-processing services. A workspace can then manage compute targets, experiments, registered models, environments, endpoints, and access permissions in a central location.
A repeatable pipeline might include ingestion, validation, feature engineering, training, evaluation, and registration. Feature engineering can transform raw events into useful signals, including interaction frequency, recency, category affinity, item popularity, and user-item similarity. For larger catalogs, item and user embeddings can represent behavioral relationships in a compact numerical form.
The training process should be reproducible. Pin the Python package versions used by the model, define the runtime environment, store configuration outside the code, and track dataset versions. Azure Machine Learning jobs can record parameters, metrics, artifacts, and model files, making it easier to compare experiments and identify the version currently serving production traffic.
A useful deployment pattern is a managed online endpoint that exposes a prediction API. The endpoint can return a ranked set of item identifiers and optional explanation data. Batch endpoints are more suitable when recommendations can be calculated periodically and stored in a database. Many applications use both: batch-generated results for speed and online scoring for newly created items or real-time context.
Select a model and measure useful results
The right algorithm depends on catalog size, interaction volume, latency requirements, and how quickly preferences change. A popularity baseline is simple and valuable because it establishes a minimum performance level. Matrix factorization can model user-item relationships efficiently, while nearest-neighbor methods are useful for “similar items” experiences. Neural approaches may capture complex patterns, but they also require more data, tuning, and operational discipline.
Content-based ranking works well when item metadata is rich. For example, an Azure learning platform could compare a user’s history of cloud and DevOps sessions with tags assigned to new sessions. Collaborative filtering may produce stronger personalization when many users interact with the same content. A hybrid ranker can combine both scores and add business rules such as availability, region, language, or freshness.
| Approach | Useful signals | Strengths | Common limitations |
|---|---|---|---|
| Popularity baseline | Views, registrations, purchases | Fast, transparent, easy to maintain | Limited personalization |
| Content-based filtering | Tags, descriptions, categories | Handles new items with metadata | Can become too narrow |
| Collaborative filtering | User-item interactions | Discovers unexpected relationships | Struggles with new users and items |
| Matrix factorization | Weighted interaction matrix | Efficient for large catalogs | Requires sufficient interaction history |
| Hybrid ranking | Behavioral and item features | Balances discovery and relevance | More complex to tune and explain |
Offline metrics should include ranking measures such as precision at k, recall at k, mean reciprocal rank, and normalized discounted cumulative gain. These metrics reveal whether relevant items appear near the top of a recommendation list. Coverage is also important because a system that recommends only a few popular items may achieve acceptable accuracy while providing poor catalog diversity.
Online evaluation adds business and user experience evidence. A controlled experiment can compare click-through rate, completion rate, registration rate, or revenue between a baseline and a new model. Guardrail metrics should monitor latency, error rate, unsubscribe behavior, and repeated exposure. A statistically stronger result is valuable only if the experience remains responsive and trustworthy.
Integrate predictions with a C# application
A C# service can call an Azure Machine Learning endpoint through an authenticated HTTP request. The application sends a structured payload containing a user identifier, recent events, context, or candidate items. The response typically includes ranked identifiers and scores. A separate application data store can then retrieve titles, images, descriptions, and links for display.
A clean integration separates recommendation logic from presentation logic. A dedicated client class can handle serialization, authentication, retries, timeouts, and response validation. Domain services can apply rules such as excluding completed courses, hiding unavailable products, or limiting repeated recommendations. Controllers or UI components should receive a ready-to-render result rather than understanding endpoint-specific details.
Configuration should be stored securely and injected into the application at runtime. Azure Key Vault can protect secrets, while managed identities can reduce the need to distribute credentials. The client should use asynchronous methods, cancellation tokens, and bounded retries for transient failures. Retry policies must avoid sending a large burst of duplicate requests when the endpoint is under pressure.
A recommendation feature should also degrade gracefully. If the endpoint is unavailable, the C# application can show popular items, recently added content, or a cached list. Caching common responses reduces latency and inference cost, but personalized results need an appropriate cache key and expiration policy. Logging should capture correlation identifiers, model version, response time, and fallback usage without exposing sensitive user data.
Operate the model as a product
Deployment is the beginning of the model’s useful life, not the end of development. User interests, item catalogs, and interaction patterns change over time. This phenomenon, commonly called data drift or concept drift, can reduce ranking quality even when the application code remains unchanged. Scheduled validation jobs should compare current data distributions with the training baseline.
Monitoring should cover both infrastructure and machine learning behavior. Track endpoint availability, CPU and memory usage, request latency, payload failures, prediction volume, and cost. At the model level, watch recommendation coverage, popularity concentration, click or completion trends, and the proportion of users receiving fallback results. Alerts can identify regressions before they become visible across the entire application.
Retraining can follow a schedule, a data-volume threshold, or a monitored performance trigger. Automated pipelines should validate the incoming data and compare the candidate model with the currently deployed version. A champion-challenger setup allows a new model to be tested against the production model before full traffic is transferred. Deployment slots or gradual rollout strategies reduce the risk of a sudden quality drop.
Responsible design also deserves attention. Recommendations can reinforce narrow patterns, hide minority interests, or expose users to content they did not expect. Add diversity constraints, provide clear controls where appropriate, and avoid using protected characteristics as shortcuts for ranking. A transparent explanation such as “recommended because you viewed cloud security sessions” can make the feature easier to understand without revealing internal model details.
Practical decisions for a first release
A small, measurable release is usually more effective than an elaborate system with unclear objectives. Start with a strong baseline, a limited catalog, and a well-defined event schema. Once the pipeline is reliable, introduce personalization and compare it with the baseline using offline and online evidence.
Useful implementation priorities include:
- Define one primary success metric and several safety metrics before training.
- Build chronological validation into the Azure Machine Learning pipeline.
- Keep a popularity or editorial fallback available in the C# application.
- Version datasets, feature definitions, runtime environments, and model artifacts.
- Monitor diversity, coverage, latency, and user behavior alongside accuracy.
The architecture can evolve as demand grows. A first version may use batch scoring and a relational database, while a larger service may add event streaming, feature stores, vector search, or real-time inference. Each new component should solve a demonstrated limitation rather than increase complexity for its own sake.
A recommendation engine becomes valuable when its predictions arrive at the right moment, fit the surrounding user experience, and improve through measured iteration. Azure Machine Learning supplies the managed experimentation and deployment capabilities, and C# connects those predictions to dependable application workflows. Begin with clean interaction data, establish a baseline, deploy a carefully monitored endpoint, and use real behavior to guide the next model version.
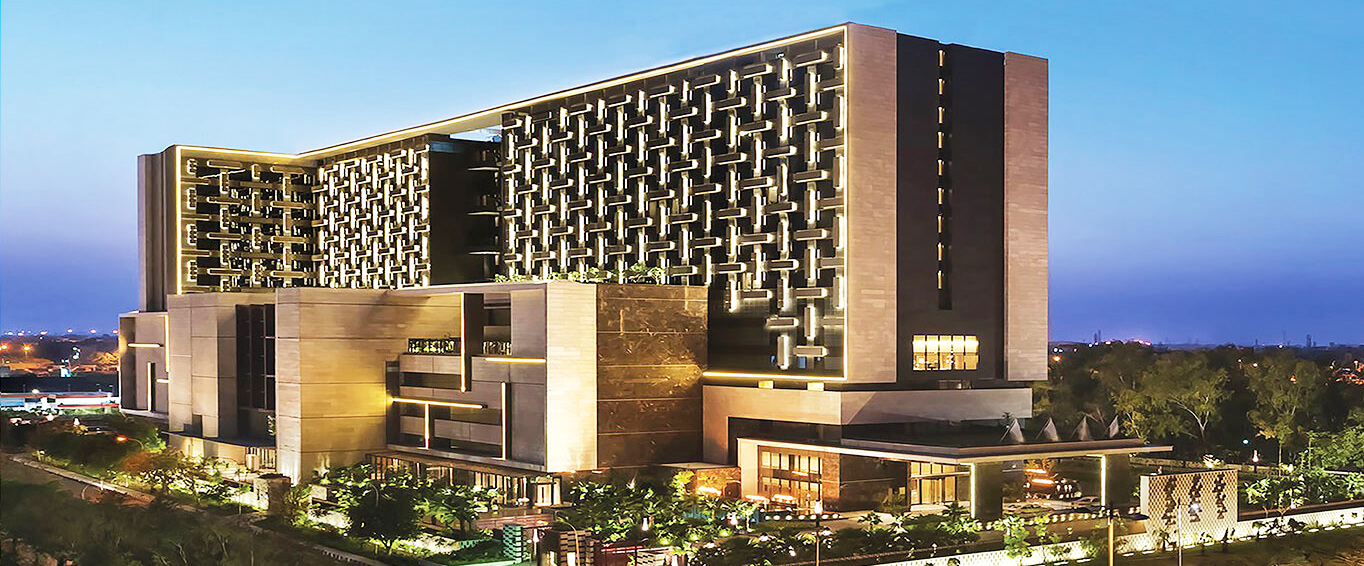
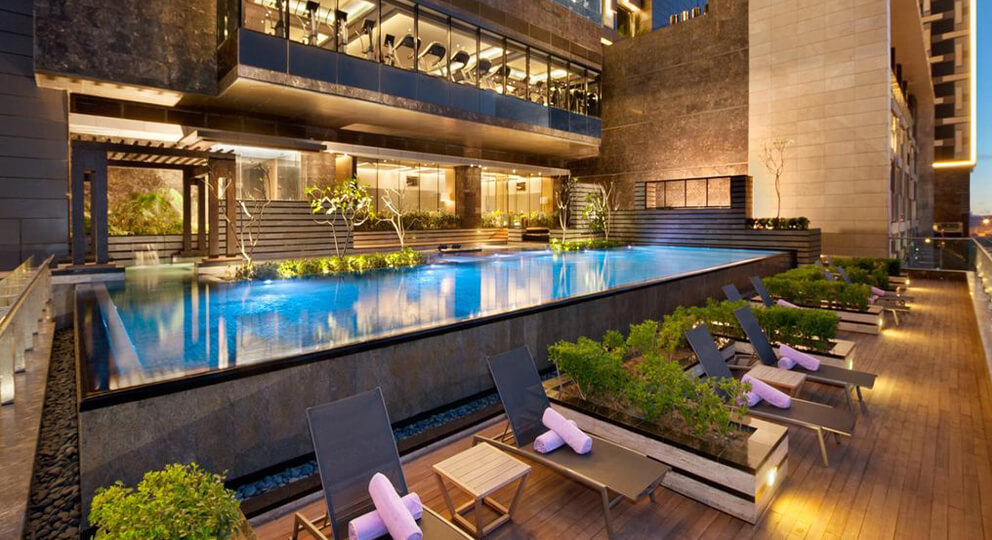
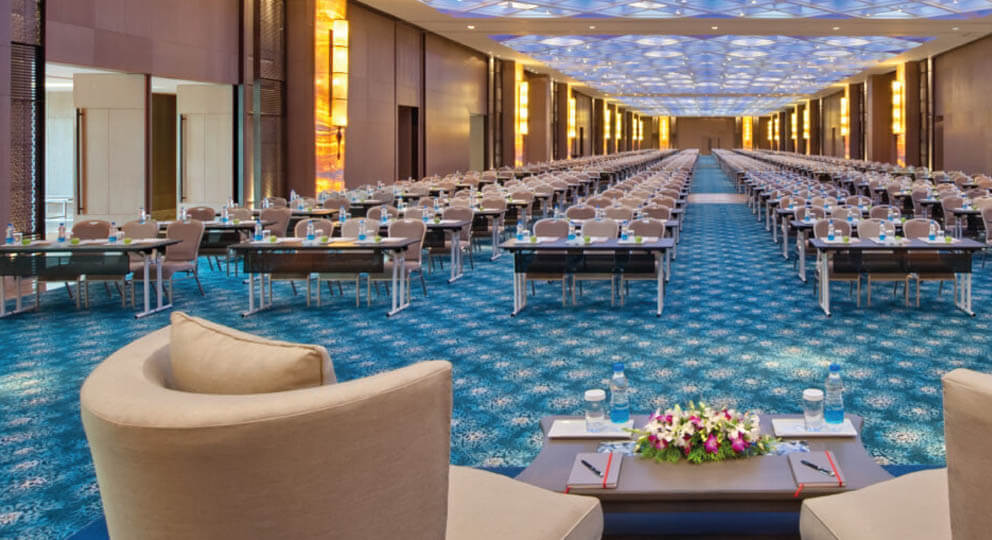
1, CBD, Maharaj Surajmal Road, Near Yamuna Sports Complex, Delhi, 110032
GENERAL QUERIES
Manish Tewatia
manish@csharpcon.com
+91-9718-431-042
TICKET QUERIES
Atul Gupta
conference@csharpcon.com
+91-9910-125-804