Presents
Magnus Mårtensson
Microsoft Regional Director, Azure MVP, CEO Loftysoft
Avirag Jain
Director & CTO R Systems
Mahesh Chand
Founder C# Corner, CEO Mindcracker
Chris Gali
CEO & Co-Founder Graphite
Subinder Khurana
Chief Architect StoryProcess, Founder NASSCOM DeepTech Club
Bryan Rishforth
Investor, Chairman Graphite
Bryn Everson
Director Biz Dev Graphite
Raj Tiwari
Digital Transformation Leader, Futurist and Visionary
Joseph Guadagno
Microsoft MVP, Lead Quicken Loans
Nikita Sachdev
Entrepreneur, Blockchain Enthusiast & Advisor, Social Media Influencer
Doug Wagner
COO & Founder Adapt Technical Group
Ritesh Modi
Architect, Senior Evangelist, Cloud Architect
Crystal Wenrick
Director Communications Mindcracker
Allen O’Neill
Microsoft MVP, Consulting Engineer/Architect
Praveen Kumar
CEO MCN Solutions
Chris Love
Founder Love2Dev, Microsoft MVP, Author
Sanjay Vyas
Microsoft Regional Director, Microsoft MVP, Founder & CEO SkillLabs Technologies
Veena Sarda
Deep Learning Consultant, Author
Sekhar Srinivasan
C# Corner MVP, Microsoft Certified Trainer, Pluralsight Author
Lalit Bansal
Founder & CEO - EIY SYS
Navdeep Garg
CEO Revinfotech
Prakash Tripathi
Tech Manager/Leader, Microsoft MVP, Blogger
Bhavna Jain
Breakthrough Consultant
Naveen Sharma
Enterprise Architect, Leadership Coach, Author
Vidya Vrat Agarwal
Principal Architect, Microsoft MVP, Author
Sheetal Agarwal
Founder Clownselors, Medical Clown, Trainer
Abhishek Kant
Founder GTM Catalyst
Vishnu Saran
Founder & CEO VoiceQube
Sandeep Soni
Founder & CEO Deccansoft, Microsoft Certified Trainer
Parveen Malik
AVP InfoSec & Vulnerability Management, Information Security Expert
Nitin Pandit
Microsoft MVP, Developer Evangelist, Author
Niloshima Srivastava
C# Corner MVP, Tech Architect, Trainer, Blogger
Bala Chirtsabesan
Senior Software Engineer at Microsoft, Author
Manoj Mittal
Sr. Technical Architect, C# Corner MVP, Author
Chandni Di
Co-Founder Voice of Slum
Vithal Wadje
Technical Lead, Microsoft MVP, Author
Shivam Ahuja
Founder SkillCircle, Business Mentor
Chervine Bhiwoo
Solution Architect, Microsoft MVP, Author
Saurabh Jain
Vice President Paytm, Founder Fun2Do Labs, Author
Vinay Solanki
Head IoT at Lenovo, Founder IoT-NCR
Anshu kumari
Founder Blockchainkids, Inventor, Trainer
Amit Singal
CEO Startup Buddy
Dev Pratap
Co-Founder & CEO Voice of Slum
Amey Vartak
Technology Consultant, Full Stack Developer, C# Corner MVP, Author
Viswanatha Swamy
Principal Software Engineer, C# Corner MVP, Author
Sanket Verma
Research Engineer @ Ballistics (Forensics) and Chair, PyData Delhi
Sourabh Somani
Lead Developer, Microsoft MVP, Author
Abhishek Mishra
Software Architect, C# Corner MVP, Author
Siddharth Vaghasia
Technical Consultant, C# Corner MVP, Blogger
Bassam Alugili
Senior Software Specialist, Database Expert
S Ravi Kumar
Solution Architect, C# Corner MVP, Author
Sundaram Subramanian
Full Stack Developer, C# Corner MVP, Speaker
Deepesh Somani
Solution Architect, Microsoft MVP, Author
Debasis Saha
Technical Project Manager, C# Corner MVP, Blogger, Author
Vipul Jain
Software Architect, C# Corner MVP, Author
Akshay Patel
Technical Architect, Microsoft Certified Trainer, C# Corner MVP, Author
Stephen Simon
RPA Developer, Evangelist, Author
Vivek Sharma
Founder Kingster636, AR/VR Specialist
Jeetendra Gund
Technical Lead, C# Corner MVP, Author
Sujal Beniwal
AI Enthusiast, Student
M Viknaraj
Microsoft MVP, Azure Architect, Author
Prasham Sabadra
Software Architect, C# Corner MVP, Trainer, Author
Aakash Maurya
Senior Developer, C# Corner MVP, Speaker
Ankit Sharma
Senior Software Engineer, C# Corner MVP, Author
Mangesh Gaherwar
Team Lead, C# Corner MVP, Author
Viral Jain
Technical Consultant, C# Corner MVP, Author
Bhasker Das
Solution Architect, Evangelist
Manish Dwivedi
Associate Project Manager
Ck Nitin
Programmer, Author
Rohit Gupta
Technical Trainer, Author
Manish Tewatia
Full-stack Marketer, UX Designer
Bhavya Gaur
Technical Illustrator
Rohit Tomar
SEO/SMO Expert
Web Track
Cloud & Data Track
Dev Track
Registration & Breakfast
Future of Desktop Apps with JS (ElectronJs)
Nitin Pandit
Building Serverless Microservices Using Microsoft Azure
Vithal Wadje
Innovating RPA: A Robot for Every Person
Stephen Simon
Managing Cloud Storage Accounts using Logic Apps
Viknaraj Manogararajah
Data visualization using Python
Sekhar Srinivasan
Going Cross platform with AR Foundation
Vivek Sharma
Keynote
Managing your Azure dependencies in ASP.NET Core apps using VS
Bala Chirtsabesan
Securing Applications on Intelligent Azure
Abhishek Mishra
Getting started with Blazor the Framework of Future
S Ravi Kumar
Lunch
Build Progressive Web Apps using Angular 9
Debasis Saha
Build and deploy to any platform using Azure DevOps
Chervine Bhiwoo
Deep Dive in Azure Service Bus
Akshay Patel
Build a Native Mobile Application using React Native and JavaScript
Joseph Guadagno
Making sense of Web Job, Web Job SDK and Functions in Azure
Prakash Tripathi
CloudFront Distribution in AWS
Viral Jain
Tea Break
Introduction to PowerBI
Aakash Maurya
Build Advanced SPFx solutions with React and Graph API
Siddharth Vaghasia
Build Business Intelligence Analyst (BIA) Skills
Sundaram Subramanian
Deep dive of Power Platform – AI BUILDER
Prasham Sabadra
Panel 1
What's new in SharePoint development
Vipul Jain
Build a SSO (Single Sign On) based Native JavaScript application with Microsoft Identity within 10 minutes
Manoj Mittal
Panel 2
Applications and working of AI
Veena Sarda
Deploying serverless API's with .Net core 3.0 on AWS & Azure
Amey Vartak
Panel 3
Blockchain with .NET Core (Ark)
Anshu Kumari
Closing Note & Prize Distribution
Dev Track
Cloud Track
Architecture Track
Emerging Tech Track
Registration & Breakfast
Creating Full-Stack Web Apps Using Server-Side Blazor
Ankit Sharma
Real time face recognition with MS Cognitive Services
Niloshima Srivastava
Building Scalable APIs with GraphQL
Jeetendra Gund
Future of development with AI and Blockchain
Navdeep Garg
Debugging Tips and Tricks with Visual Studio 2019
Joseph Guadagno
Azure Containers
Abhishek Kant
Enterprise Architecture
Naveen Sharma
Bot Framework - learn it fast and look like a boss!
Allen O’Neill
Keynote
.Net Core & C# 8 Performance
David McCarter
Working with Azure kubernetes services
Ritesh Modi
Becoming an Architect
Vidyavrat Agarwal
Why Techies Need to Learn Product Management
Saurabh Jain
Lunch
Build a rules engine in .Net Core
Sanjay Vyas
Building CI and CD Pipeline using Azure DevOps
Sandeep Soni
Entity Framework Core - Tips and Tricks, Performance Optimization, and Tuning
Bassam Alugili
Hacking your way into Data Science
Sanket Verma
Speed up your .Net Core Website
Sourabh Somani
Azure
Magnus Mårtensson
Demystifying Open Distro for Elasticsearch
Suman Debnath
Future of Data
Shivam Ahuja
Tea Break
gRPC with C# and .Net Core
Mangesh Gaherwar
Panel 1
Essentials of Cloud security
Parveen Malik
Power platform and Dynamics 365
Deepesh Somani
Microservices - the gRPC Way
Viswanatha Swamy
Panel 2
Reserved
Reserved
Closing Note & Prize Distribution
Using Azure Cosmos DB for high-throughput data solutions
Modern applications generate data continuously. Telemetry, product events, financial transactions, customer interactions, and device signals can arrive in large bursts, then remain active around the clock. A database designed for occasional reads and modest write volumes can become a bottleneck when traffic grows across regions and application instances.
Azure Cosmos DB is a globally distributed NoSQL database service designed for low-latency access, elastic throughput, and operational resilience. Its flexible data models and multiple APIs make it suitable for web applications, Internet of Things platforms, real-time analytics pipelines, and event-driven systems.
A successful implementation depends on more than selecting a cloud database. Data modeling, partition-key design, request-unit budgeting, consistency choices, indexing, and application behavior all influence the final result. These decisions are especially relevant to developers exploring cloud and distributed systems through the conference agenda, where architecture and implementation practices are central themes.
Why throughput requires a distributed design
Throughput describes how much work a system can process during a given period. For a database, that work includes reads, inserts, updates, deletes, queries, and transactional operations. High throughput is often measured alongside latency, since a system that handles many requests but responds slowly may still fail application requirements.
Cosmos DB uses request units, commonly called RUs, to represent the compute, memory, and input/output resources consumed by database operations. A simple point read using an item identifier and partition key normally consumes fewer RUs than a cross-partition query, a large document update, or a query that requires extensive filtering and sorting.
Distributed storage allows workloads to scale beyond the limits of a single database server. Cosmos DB distributes data across physical partitions and can replicate that data across Azure regions. Applications can therefore place data close to users, tolerate regional failures, and increase provisioned or autoscale throughput as demand changes.
The distributed model introduces design responsibilities. A poor partition key can concentrate activity on one partition, creating a hot partition while other capacity remains idle. Efficient high-throughput architecture begins by understanding access patterns before creating containers or writing application code.
Model data around access patterns
Cosmos DB supports document-oriented designs in which related values can be stored together in a JSON document. This approach can reduce joins and allow an application to retrieve an aggregate with a single point read. For example, an order document may contain customer information, line items, payment status, and fulfillment details when those values are commonly accessed together.
Embedding data is useful when child records are bounded and updated with the parent. Referencing is safer when related data grows without a predictable limit or changes independently. A continuously expanding array of events inside one document can eventually create large item sizes, expensive updates, and contention. In that case, separate event documents are usually more appropriate.
A practical design starts with questions such as which fields identify an item, which requests are most frequent, which operations must be transactional, and whether records have a natural lifecycle. These answers guide the choice of partition key, indexing policy, time-to-live settings, and API model.
Cosmos DB supports logical partitioning, so all items with the same partition-key value belong to one logical partition. A good key has high cardinality, distributes writes evenly, and appears in the application’s most common queries. Tenant ID, device ID, customer ID, or a carefully selected geographic value may work, depending on traffic distribution.
Choose a partition key for sustained load
Partition-key selection is one of the most important decisions in a Cosmos DB deployment because changing it later can require data migration. A key should distribute both storage and request volume. A field with millions of possible values may be better than a field with only a few values, provided the application commonly uses it.
Cardinality alone is not enough. A globally unique identifier may distribute data well but create inefficient queries if users usually search by tenant, account, or device. Conversely, a tenant identifier may support efficient tenant-scoped requests but become a hot key when one customer generates most of the workload.
High-ingestion systems often use a hierarchical or synthetic strategy. A partition value can combine stable identity with a time bucket, such as a device identifier and day, when a single device produces a large event stream. Time bucketing limits the concentration of writes while preserving useful query boundaries.
Cross-partition queries should be treated as intentional operations rather than an accidental consequence of the data model. They can be appropriate for administrative reports or background processing, but they should not be the default path for latency-sensitive user requests. Include the partition key in point reads and targeted queries whenever possible.
| Design concern | Practical choice | Effect on a high-throughput workload |
|---|---|---|
| Item retrieval | Use item ID with partition key | Delivers predictable, low-latency point reads |
| Write distribution | Select a high-cardinality, balanced key | Reduces hot partitions and uneven capacity |
| Large event streams | Use time buckets or a composite value | Prevents one logical partition from growing too quickly |
| Tenant isolation | Partition by tenant when traffic is balanced | Simplifies scoped queries and operational boundaries |
| Reporting queries | Run asynchronously or through an analytical path | Keeps interactive traffic from consuming excessive RUs |
| Capacity planning | Use autoscale for variable demand | Handles bursts while limiting unused provisioned capacity |
Balance consistency, indexing, and cost
Cosmos DB offers several consistency levels that represent different trade-offs between read freshness, latency, availability, and complexity. Strong consistency provides the strictest read guarantees within its supported configuration. Session consistency is frequently useful for user-facing applications because a client can immediately observe its own writes while avoiding the broad cost of strong global coordination.
Eventual consistency can suit workloads where small delays are acceptable, such as social activity feeds, analytics dashboards, or replicated reference views. Bounded staleness provides a controlled limit on how old a read may be. The appropriate choice depends on business rules rather than a general preference for either strict or relaxed consistency.
Indexing also affects RU consumption. Automatic indexing is convenient for evolving document schemas, but indexing every property can increase write costs and storage requirements. An indexing policy should reflect actual query patterns. Excluding large text fields, volatile properties, or fields that are never filtered can reduce unnecessary work.
Measure before making aggressive exclusions. A field that is not queried today may become important later, and changing indexing policies can trigger background transformation activity. Use query metrics, request-charge headers, Azure Monitor, and representative load tests to evaluate whether an indexing change improves the overall workload.
Build applications that cooperate with the service
High-throughput database performance depends on client behavior as much as server capacity. In .NET applications, reuse the CosmosClient instance rather than creating a new client for every request. A shared client manages connections efficiently and supports the service’s distributed architecture.
Use asynchronous APIs for network operations and keep request paths free from avoidable blocking. Point reads are generally preferable to queries when the item identifier and partition key are known. For bulk ingestion, batch or bulk execution can reduce application overhead and improve the efficiency of large write workloads.
Transient failures and throttling are expected possibilities in a distributed service. Applications should use the SDK’s retry behavior while still applying sensible limits and observing response metadata. A retry storm can amplify an outage, so workloads need controlled concurrency, backoff, cancellation, and clear operational logging.
Transactional batch operations are valuable when multiple items share a logical partition and must succeed together. They are not a substitute for distributed transactions across arbitrary partition keys. If a workflow spans several partitions or services, use an event-driven process, an outbox pattern, or compensating actions to preserve reliability.
Scale capacity with measurable signals
Cosmos DB can use provisioned throughput, autoscale throughput, or serverless capacity depending on workload size and variability. Provisioned throughput is useful for stable, predictable traffic. Autoscale is a strong fit for applications with recurring peaks, such as business-hour workloads or scheduled campaigns. Serverless can suit sporadic workloads with limited sustained volume.
Capacity planning should include reads, writes, document size, query complexity, indexing, and replication requirements. A test that inserts tiny documents may produce very different RU consumption from production documents containing nested arrays, metadata, and larger payloads. Test with realistic distributions rather than average values alone.
Monitor normalized RU consumption, throttled requests, latency percentiles, physical partition behavior, storage growth, and regional availability. Average latency can hide a serious tail problem, so p95 and p99 measurements are important for customer-facing services. Alerts should identify rising consumption before the system reaches persistent throttling.
Change one major variable at a time during performance testing. Compare partition-key alternatives, indexing policies, consistency levels, and concurrency limits against the same workload. This produces evidence that can guide architectural decisions instead of relying on isolated benchmark numbers.
Apply resilient patterns to real workloads
A high-throughput solution often separates ingestion from processing. An API can accept validated events, write them efficiently to Cosmos DB, and publish work for downstream consumers through Azure messaging services. This keeps user-facing latency predictable while allowing enrichment, aggregation, and notification tasks to proceed independently.
Time-to-live is useful for temporary records, session state, idempotency markers, and short-lived telemetry. Expiration policies prevent old data from accumulating indefinitely, though deletion activity still has resource implications. Long-term retention may be better handled by moving historical data to Azure Blob Storage or an analytical platform.
Change feed processing enables downstream services to react to inserts and updates without repeatedly scanning containers. It can support search indexing, materialized views, event-driven workflows, and data export. Consumers should be idempotent because retries, restarts, and partial processing are normal parts of distributed operation.
Security belongs in the design from the beginning. Use managed identities where possible, store secrets in Azure Key Vault, apply least-privilege access, and configure private connectivity for sensitive workloads. Regional replication, backup policies, and recovery procedures should be tested rather than treated as configuration details that need attention only during an incident.
Recommendations for a production-ready deployment
A disciplined rollout connects architecture decisions to measurable workload behavior. The following practices provide a practical foundation:
- Select a partition key using expected request volume, cardinality, storage growth, and query scope.
- Benchmark realistic document sizes, concurrency levels, payload distributions, and peak traffic patterns.
- Prefer point reads and partition-scoped queries for interactive application paths.
- Tune indexing policies and consistency levels according to measured access requirements.
- Monitor RU usage, throttling, latency percentiles, storage, and regional health with actionable alerts.
Document the reasoning behind each major choice, including why a partition key was selected and which queries it supports. This record helps future developers avoid introducing cross-partition scans or uneven write patterns as the application evolves.
Review capacity after meaningful product changes. A new reporting feature, larger document shape, additional region, or increased retention period can alter RU consumption substantially. Treat Cosmos DB configuration as part of the application’s lifecycle rather than a one-time infrastructure decision.
Azure Cosmos DB can provide a strong foundation for globally distributed, low-latency systems when the workload is modeled for its strengths. Developers who combine careful partitioning, efficient client behavior, measured capacity planning, and resilient processing patterns can turn elastic cloud storage into a dependable high-throughput data platform. Explore the conference resources and technical sessions at C# Corner Annual Conference to continue building practical expertise in Azure, distributed systems, and modern application architecture.
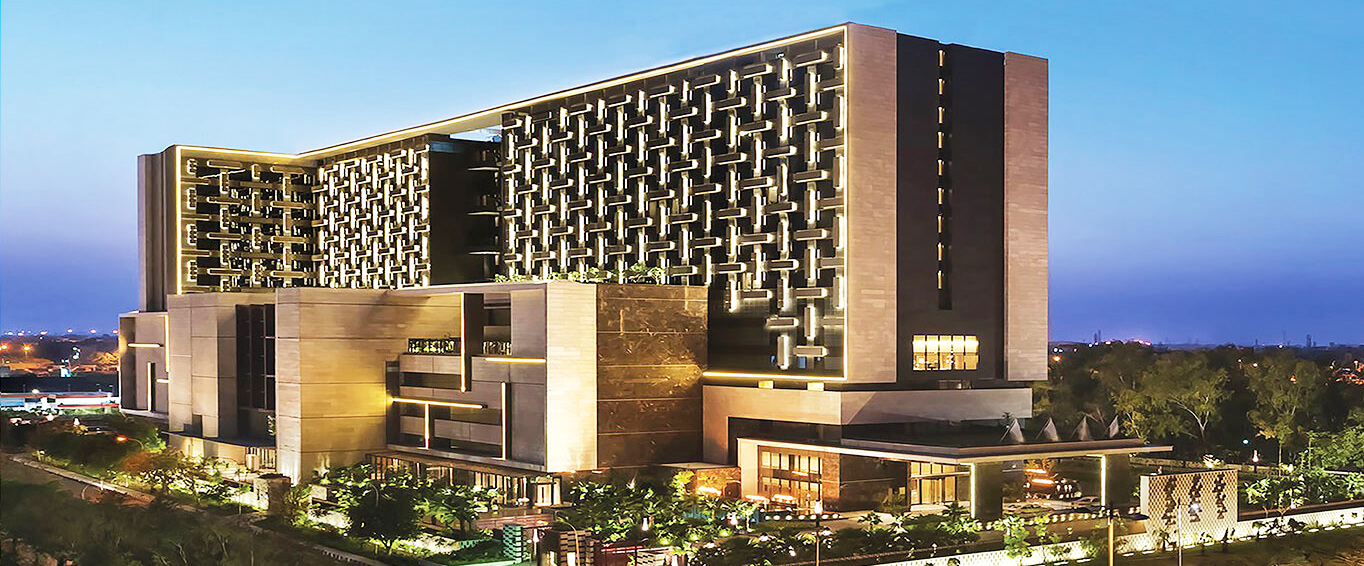
1, CBD, Maharaj Surajmal Road, Near Yamuna Sports Complex, Delhi, 110032
GENERAL QUERIES
Manish Tewatia
manish@csharpcon.com
+91-9718-431-042
TICKET QUERIES
Atul Gupta
conference@csharpcon.com
+91-9910-125-804