Presents
Magnus Mårtensson
Microsoft Regional Director, Azure MVP, CEO Loftysoft
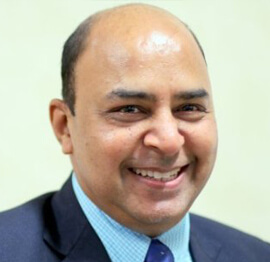
Avirag Jain
Director & CTO R Systems
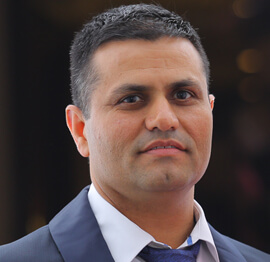
Mahesh Chand
Founder C# Corner, CEO Mindcracker
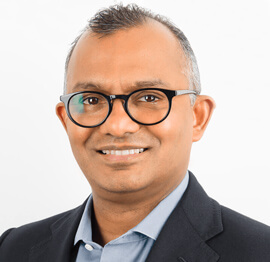
Chris Gali
CEO & Co-Founder Graphite
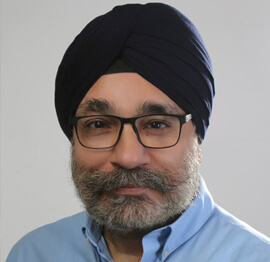
Subinder Khurana
Chief Architect StoryProcess, Founder NASSCOM DeepTech Club
Bryan Rishforth
Investor, Chairman Graphite
Bryn Everson
Director Biz Dev Graphite
Raj Tiwari
Digital Transformation Leader, Futurist and Visionary
Joseph Guadagno
Microsoft MVP, Lead Quicken Loans
Nikita Sachdev
Entrepreneur, Blockchain Enthusiast & Advisor, Social Media Influencer
Doug Wagner
COO & Founder Adapt Technical Group
Ritesh Modi
Architect, Senior Evangelist, Cloud Architect
Crystal Wenrick
Director Communications Mindcracker
Allen O’Neill
Microsoft MVP, Consulting Engineer/Architect
Praveen Kumar
CEO MCN Solutions
Chris Love
Founder Love2Dev, Microsoft MVP, Author
Sanjay Vyas
Microsoft Regional Director, Microsoft MVP, Founder & CEO SkillLabs Technologies
Veena Sarda
Deep Learning Consultant, Author
Sekhar Srinivasan
C# Corner MVP, Microsoft Certified Trainer, Pluralsight Author
Lalit Bansal
Founder & CEO - EIY SYS
Navdeep Garg
CEO Revinfotech
Prakash Tripathi
Tech Manager/Leader, Microsoft MVP, Blogger
Bhavna Jain
Breakthrough Consultant
Naveen Sharma
Enterprise Architect, Leadership Coach, Author
Vidya Vrat Agarwal
Principal Architect, Microsoft MVP, Author
Sheetal Agarwal
Founder Clownselors, Medical Clown, Trainer
Abhishek Kant
Founder GTM Catalyst
Vishnu Saran
Founder & CEO VoiceQube
Sandeep Soni
Founder & CEO Deccansoft, Microsoft Certified Trainer
Parveen Malik
AVP InfoSec & Vulnerability Management, Information Security Expert
Nitin Pandit
Microsoft MVP, Developer Evangelist, Author
Niloshima Srivastava
C# Corner MVP, Tech Architect, Trainer, Blogger
Bala Chirtsabesan
Senior Software Engineer at Microsoft, Author
Manoj Mittal
Sr. Technical Architect, C# Corner MVP, Author
Chandni Di
Co-Founder Voice of Slum
Vithal Wadje
Technical Lead, Microsoft MVP, Author
Shivam Ahuja
Founder SkillCircle, Business Mentor
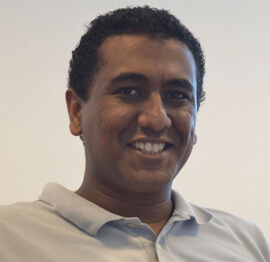
Chervine Bhiwoo
Solution Architect, Microsoft MVP, Author
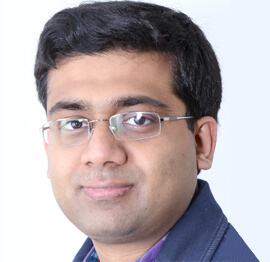
Saurabh Jain
Vice President Paytm, Founder Fun2Do Labs, Author
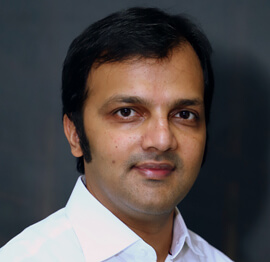
Vinay Solanki
Head IoT at Lenovo, Founder IoT-NCR
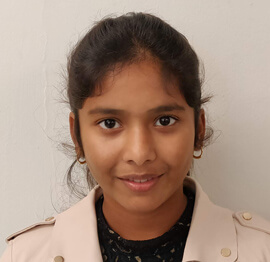
Anshu kumari
Founder Blockchainkids, Inventor, Trainer
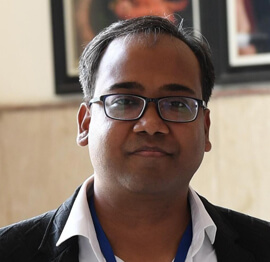
Amit Singal
CEO Startup Buddy
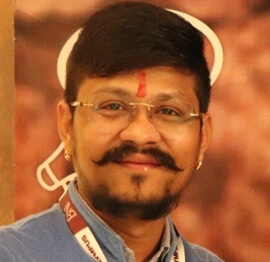
Dev Pratap
Co-Founder & CEO Voice of Slum
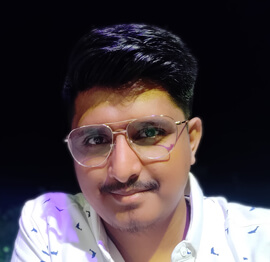
Amey Vartak
Technology Consultant, Full Stack Developer, C# Corner MVP, Author
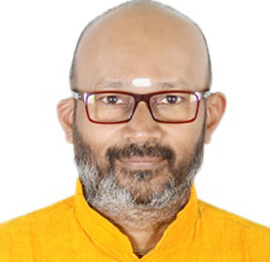
Viswanatha Swamy
Principal Software Engineer, C# Corner MVP, Author
Sanket Verma
Research Engineer @ Ballistics (Forensics) and Chair, PyData Delhi
Sourabh Somani
Lead Developer, Microsoft MVP, Author
Abhishek Mishra
Software Architect, C# Corner MVP, Author
Siddharth Vaghasia
Technical Consultant, C# Corner MVP, Blogger
Bassam Alugili
Senior Software Specialist, Database Expert
S Ravi Kumar
Solution Architect, C# Corner MVP, Author
Sundaram Subramanian
Full Stack Developer, C# Corner MVP, Speaker
Deepesh Somani
Solution Architect, Microsoft MVP, Author
Debasis Saha
Technical Project Manager, C# Corner MVP, Blogger, Author
Vipul Jain
Software Architect, C# Corner MVP, Author
Akshay Patel
Technical Architect, Microsoft Certified Trainer, C# Corner MVP, Author
Stephen Simon
RPA Developer, Evangelist, Author
Vivek Sharma
Founder Kingster636, AR/VR Specialist
Jeetendra Gund
Technical Lead, C# Corner MVP, Author
Sujal Beniwal
AI Enthusiast, Student
M Viknaraj
Microsoft MVP, Azure Architect, Author
Prasham Sabadra
Software Architect, C# Corner MVP, Trainer, Author
Aakash Maurya
Senior Developer, C# Corner MVP, Speaker
Ankit Sharma
Senior Software Engineer, C# Corner MVP, Author
Mangesh Gaherwar
Team Lead, C# Corner MVP, Author
Viral Jain
Technical Consultant, C# Corner MVP, Author
Bhasker Das
Solution Architect, Evangelist
Manish Dwivedi
Associate Project Manager
Ck Nitin
Programmer, Author
Rohit Gupta
Technical Trainer, Author
Manish Tewatia
Full-stack Marketer, UX Designer
Bhavya Gaur
Technical Illustrator
Rohit Tomar
SEO/SMO Expert
Web Track
Cloud & Data Track
Dev Track
Registration & Breakfast
Future of Desktop Apps with JS (ElectronJs)
Nitin Pandit
Building Serverless Microservices Using Microsoft Azure
Vithal Wadje
Innovating RPA: A Robot for Every Person
Stephen Simon
Managing Cloud Storage Accounts using Logic Apps
Viknaraj Manogararajah
Data visualization using Python
Sekhar Srinivasan
Going Cross platform with AR Foundation
Vivek Sharma
Keynote
Managing your Azure dependencies in ASP.NET Core apps using VS
Bala Chirtsabesan
Securing Applications on Intelligent Azure
Abhishek Mishra
Getting started with Blazor the Framework of Future
S Ravi Kumar
Lunch
Build Progressive Web Apps using Angular 9
Debasis Saha
Build and deploy to any platform using Azure DevOps
Chervine Bhiwoo
Deep Dive in Azure Service Bus
Akshay Patel
Build a Native Mobile Application using React Native and JavaScript
Joseph Guadagno
Making sense of Web Job, Web Job SDK and Functions in Azure
Prakash Tripathi
CloudFront Distribution in AWS
Viral Jain
Tea Break
Introduction to PowerBI
Aakash Maurya
Build Advanced SPFx solutions with React and Graph API
Siddharth Vaghasia
Build Business Intelligence Analyst (BIA) Skills
Sundaram Subramanian
Deep dive of Power Platform – AI BUILDER
Prasham Sabadra
Panel 1
What's new in SharePoint development
Vipul Jain
Build a SSO (Single Sign On) based Native JavaScript application with Microsoft Identity within 10 minutes
Manoj Mittal
Panel 2
Applications and working of AI
Veena Sarda
Deploying serverless API's with .Net core 3.0 on AWS & Azure
Amey Vartak
Panel 3
Blockchain with .NET Core (Ark)
Anshu Kumari
Closing Note & Prize Distribution
Dev Track
Cloud Track
Architecture Track
Emerging Tech Track
Registration & Breakfast
Creating Full-Stack Web Apps Using Server-Side Blazor
Ankit Sharma
Real time face recognition with MS Cognitive Services
Niloshima Srivastava
Building Scalable APIs with GraphQL
Jeetendra Gund
Future of development with AI and Blockchain
Navdeep Garg
Debugging Tips and Tricks with Visual Studio 2019
Joseph Guadagno
Azure Containers
Abhishek Kant
Enterprise Architecture
Naveen Sharma
Bot Framework - learn it fast and look like a boss!
Allen O’Neill
Keynote
.Net Core & C# 8 Performance
David McCarter
Working with Azure kubernetes services
Ritesh Modi
Becoming an Architect
Vidyavrat Agarwal
Why Techies Need to Learn Product Management
Saurabh Jain
Lunch
Build a rules engine in .Net Core
Sanjay Vyas
Building CI and CD Pipeline using Azure DevOps
Sandeep Soni
Entity Framework Core - Tips and Tricks, Performance Optimization, and Tuning
Bassam Alugili
Hacking your way into Data Science
Sanket Verma
Speed up your .Net Core Website
Sourabh Somani
Azure
Magnus Mårtensson
Demystifying Open Distro for Elasticsearch
Suman Debnath
Future of Data
Shivam Ahuja
Tea Break
gRPC with C# and .Net Core
Mangesh Gaherwar
Panel 1
Essentials of Cloud security
Parveen Malik
Power platform and Dynamics 365
Deepesh Somani
Microservices - the gRPC Way
Viswanatha Swamy
Panel 2
Reserved
Reserved
Closing Note & Prize Distribution
Building Intelligent Search Features With Azure Cognitive Search
Search has become a core part of modern software design. Users expect to find relevant products, documents, support answers, and records even when their wording does not exactly match the stored content. A simple database query may return technically correct results while still failing to understand intent, context, or business priorities.
Azure Cognitive Search gives development teams a managed foundation for richer discovery experiences. It combines indexing, full-text search, filters, scoring, autocomplete, semantic understanding, and optional AI enrichment in one Azure service. This makes it suitable for portals, knowledge bases, commerce applications, document libraries, and enterprise systems.
For software professionals attending a technology event such as C# Corner Annual Conference 2020, the service connects several important themes: cloud computing, artificial intelligence, data engineering, web development, and DevOps. The best results come from treating search as a product feature with a clear information model, measurable outcomes, and continuous refinement.
Why Search Needs Intelligence
A conventional keyword search usually compares a query with text fields and returns records containing matching terms. That approach works for exact names or identifiers, but it becomes less effective when users employ synonyms, abbreviations, alternate spellings, or natural-language questions. Someone searching for “laptop repair” may expect results about device support, hardware service, or warranty assistance.
Intelligent search improves the path from a user’s language to useful content. Azure Cognitive Search can analyze text, recognize linguistic patterns, apply scoring profiles, and use filters to narrow results by category, date, location, or access level. These capabilities help the application interpret the structure around a query instead of treating every word as equally important.
Relevance also depends on the organization’s goals. A retailer may promote in-stock products, while an internal knowledge portal may prioritize recently approved policies. Search quality is therefore a combination of language processing, data quality, ranking logic, and user experience. The service provides the tools, but the development team defines what “useful” means.
Core Azure Search Architecture
An Azure Cognitive Search solution typically contains a data source, an index, an indexer, and a search client. The data source identifies content in services such as Azure Blob Storage, Azure SQL Database, Cosmos DB, or another supported repository. The index describes the searchable fields, their data types, and the operations allowed on each field.
An indexer extracts and transforms data on a schedule. It can detect new or changed records and populate the search index without requiring a custom synchronization pipeline for every source. For more specialized workflows, applications can push documents directly through the Search Documents API. This approach is useful when data arrives from event streams, external services, or transactional workflows.
A field may be searchable, filterable, sortable, facetable, retrievable, or any combination of these settings. Searchable fields are analyzed for text matching, whereas filterable fields support exact restrictions. Facets produce counts such as product categories or document types, giving users a way to refine results. Selecting these attributes carefully keeps the index efficient and aligns its behavior with the interface.
Skillsets extend the indexing pipeline with AI enrichment. They can extract text from files, detect language, identify entities, generate key phrases, and process images through connected cognitive services. The enriched output can then be stored in searchable fields, allowing users to discover information that was not explicitly modeled in the original source.
Choosing Search Features And Trade-Offs
Different search capabilities solve different problems. Full-text search is usually the foundation, while autocomplete and suggestions help users formulate queries. Filters and facets support navigation through structured data. Semantic ranking and vector retrieval can improve results when matching meaning matters more than exact words.
| Capability | Best Use | Main Benefit | Design Consideration |
|---|---|---|---|
| Full-text search | Articles, products, records, and documents | Matches terms across analyzed content | Requires suitable analyzers and field configuration |
| Autocomplete | Search boxes and catalog navigation | Helps users complete queries quickly | Suggestions must be based on useful fields |
| Filters and facets | Commerce and enterprise portals | Gives users structured refinement | Depends on clean metadata |
| Semantic ranking | Natural-language queries | Improves relevance and readability | Needs careful evaluation and suitable content |
| Vector search | Similarity and concept-based discovery | Finds related meaning beyond exact terms | Requires embeddings and a thoughtful retrieval strategy |
| AI enrichment | Scanned files, images, and unstructured content | Adds searchable knowledge to raw data | Adds processing cost and pipeline complexity |
Semantic search is helpful when users phrase questions conversationally or when relevant documents use different terminology. Vector search goes further by representing content and queries as numerical embeddings, then retrieving items with similar meaning. Hybrid search combines lexical and vector approaches, which often provides a stronger baseline because exact identifiers and conceptual relationships can both matter.
Every feature introduces cost, latency, or maintenance requirements. A small product catalog may gain little from a complex vector pipeline, while a legal document repository may benefit substantially from semantic and AI-assisted retrieval. Teams should test features against representative queries rather than selecting them solely because they are available.
Designing A Strong Searchable Index
Good search begins with a clear content model. Identify the fields users search, the fields they filter, the values they need to see in results, and the metadata that should affect ranking. For a support portal, this might include title, article body, product family, issue type, publication date, language, author, and approval status.
Text analysis should match the content and audience. Language-specific analyzers can handle stemming, stop words, and linguistic variations. Custom analyzers may be appropriate for product codes, part numbers, or technical identifiers where punctuation and capitalization carry meaning. Synonym maps can connect terms such as “cloud storage” and “object storage,” although they should be governed carefully to avoid irrelevant matches.
Indexing unstructured content requires an enrichment plan. A document pipeline might extract text from PDFs, split long material into sections, identify entities, and generate embeddings for each chunk. Chunking is especially important for question answering because an entire large document may be too broad to retrieve accurately. Each chunk should retain enough context to make the result understandable.
Security deserves attention before data reaches the index. Search results must respect document permissions, tenant boundaries, and regional restrictions. Common approaches include filtering by security identifiers at query time or creating separate indexes for strongly isolated audiences. Returning a restricted document briefly, even through a preview or facet count, can become a serious privacy issue.
Creating A Useful Search Experience
The search interface should expose the service’s strengths without overwhelming users. A responsive search box can provide autocomplete after a few characters, while suggested queries can guide users toward recognized concepts. Result cards should display highlighted matching text, meaningful metadata, and a clear path to the original record.
Filters should reflect real decision points rather than every available field. Facets for content type, department, date, or product family can shorten the route to an answer. Query spelling correction, synonym handling, and friendly zero-result messages help users recover when their first attempt does not match the index.
Search results should be measured through observable behavior. Useful signals include click-through rate, successful document opens, reformulation frequency, abandonment, and time to the selected result. A low click rate may indicate poor ranking, weak titles, or inaccurate snippets. A high reformulation rate may reveal missing synonyms or unclear filters.
For applications built with .NET, the Azure SDK can keep search operations within familiar C# patterns. Developers should isolate search calls behind an application service, validate user-provided filters, and avoid exposing administrative keys in browser code. Pagination, retry handling, cancellation, and telemetry belong in the application design from the beginning.
Connecting Search With Modern Web Applications
A search service becomes valuable when it is integrated into a fast, accessible interface. Server-rendered applications, single-page applications, and Blazor solutions can all consume search APIs through a controlled backend. The client should receive only the fields needed for display, while authentication and authorization remain under the application’s control.
Search-driven pages often need URL-addressable state. A query, selected facets, sort order, and page number can be represented in the URL so that users can bookmark or share a result set. This also supports browser navigation and improves usability on multi-page research tasks. Loading indicators and progressive rendering prevent the interface from feeling unresponsive during complex queries.
The presentation layer should be designed around the content model. A document search may need highlighted passages and document types, while a commerce search may prioritize images, prices, availability, and ratings. Developers exploring a component-based Microsoft web stack can also review this Blazor WebAssembly guide when considering how a browser application might present search results and interactive filters.
Accessibility remains essential. Search inputs need labels, result updates should be announced appropriately, keyboard users must be able to reach filters, and highlighted text should retain sufficient contrast. A visually impressive result page still fails if users cannot navigate it efficiently with assistive technology.
Operating Relevance And Search Quality
Search quality changes as content, terminology, and user expectations evolve. Indexing schedules should reflect how quickly source data changes, while monitoring should detect failed indexers, rejected documents, throttling, and unusual query latency. Azure monitoring tools can connect operational data with application telemetry to reveal where the search journey breaks down.
Relevance tuning is an iterative discipline. Scoring profiles can boost recent, popular, authoritative, or commercially important content. However, excessive boosting may hide useful results. Teams should create a test set of representative queries, record expected results, and compare ranking changes before releasing them to all users.
Cost control depends on the service tier, replica and partition choices, enrichment volume, query traffic, and storage requirements. Replicas support query throughput and availability, while partitions provide capacity for larger indexes. AI enrichment and vector storage can increase resource consumption, so teams should estimate growth and archive obsolete content.
A practical deployment pipeline treats index definitions, skillsets, synonym maps, and scoring profiles as versioned assets. Infrastructure automation makes environments reproducible and supports controlled changes. Blue-green index deployment can reduce disruption when a schema change requires rebuilding the index, allowing the application to switch to the new version after validation.
Practical Steps For A Reliable Implementation
Begin with a narrow, measurable search scenario rather than indexing every source at once. A focused pilot makes it easier to inspect documents, test queries, compare ranking behavior, and identify gaps in metadata. Once the basic workflow is reliable, add enrichment, semantic ranking, or vector retrieval where evidence supports the investment.
Useful implementation priorities include:
- Define the most important user journeys and representative queries before choosing advanced features.
- Separate searchable text, filterable metadata, sortable values, and display-only fields in the index schema.
- Protect tenant and document permissions through query-time security filters or isolated indexes.
- Track zero-result queries, reformulations, click behavior, latency, and indexing failures.
- Version analyzers, synonym maps, scoring profiles, and index definitions through the deployment pipeline.
The strongest search projects include domain experts in evaluation. Subject-matter specialists can identify whether a result is genuinely useful, while developers can connect that feedback to analyzers, fields, ranking, or source-data problems. A shared review process prevents teams from relying on a single generic relevance score.
Intelligent search is an ongoing capability rather than a one-time configuration. As new content arrives and users develop new vocabulary, the index and ranking strategy must adapt. Azure Cognitive Search supplies a scalable platform for that evolution, provided the surrounding application treats relevance, privacy, usability, and operations as connected concerns.
Build a small Azure search prototype around a real content set, measure its results with realistic queries, and refine the index based on user behavior. Then expand the experience with semantic understanding, AI enrichment, or vector retrieval where those capabilities produce clear value for your application.
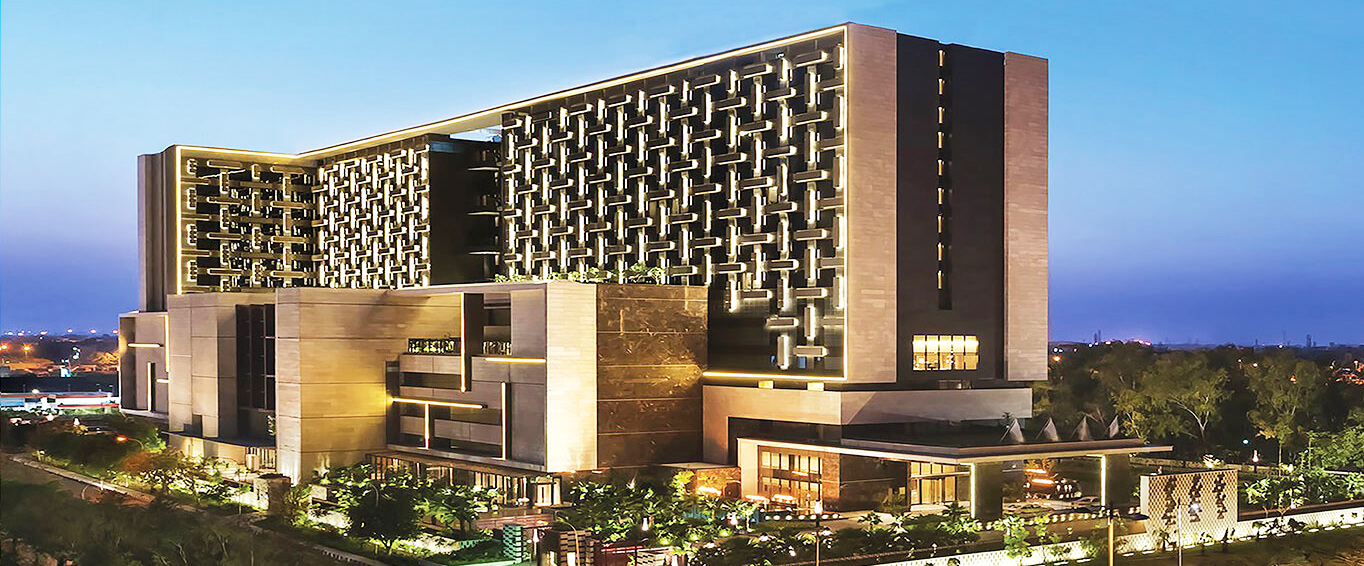
1, CBD, Maharaj Surajmal Road, Near Yamuna Sports Complex, Delhi, 110032
GENERAL QUERIES
Manish Tewatia
manish@csharpcon.com
+91-9718-431-042
TICKET QUERIES
Atul Gupta
conference@csharpcon.com
+91-9910-125-804