Presents
Magnus Mårtensson
Microsoft Regional Director, Azure MVP, CEO Loftysoft
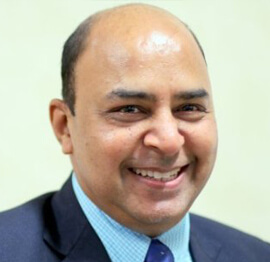
Avirag Jain
Director & CTO R Systems
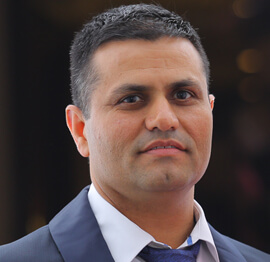
Mahesh Chand
Founder C# Corner, CEO Mindcracker
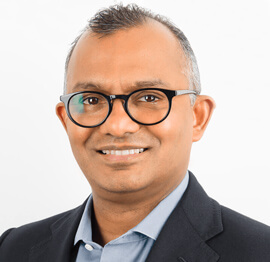
Chris Gali
CEO & Co-Founder Graphite
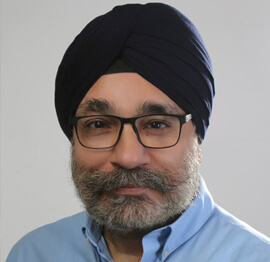
Subinder Khurana
Chief Architect StoryProcess, Founder NASSCOM DeepTech Club
Bryan Rishforth
Investor, Chairman Graphite
Bryn Everson
Director Biz Dev Graphite
Raj Tiwari
Digital Transformation Leader, Futurist and Visionary
Joseph Guadagno
Microsoft MVP, Lead Quicken Loans
Nikita Sachdev
Entrepreneur, Blockchain Enthusiast & Advisor, Social Media Influencer
Doug Wagner
COO & Founder Adapt Technical Group
Ritesh Modi
Architect, Senior Evangelist, Cloud Architect
Crystal Wenrick
Director Communications Mindcracker
Allen O’Neill
Microsoft MVP, Consulting Engineer/Architect
Praveen Kumar
CEO MCN Solutions
Chris Love
Founder Love2Dev, Microsoft MVP, Author
Sanjay Vyas
Microsoft Regional Director, Microsoft MVP, Founder & CEO SkillLabs Technologies
Veena Sarda
Deep Learning Consultant, Author
Sekhar Srinivasan
C# Corner MVP, Microsoft Certified Trainer, Pluralsight Author
Lalit Bansal
Founder & CEO - EIY SYS
Navdeep Garg
CEO Revinfotech
Prakash Tripathi
Tech Manager/Leader, Microsoft MVP, Blogger
Bhavna Jain
Breakthrough Consultant
Naveen Sharma
Enterprise Architect, Leadership Coach, Author
Vidya Vrat Agarwal
Principal Architect, Microsoft MVP, Author
Sheetal Agarwal
Founder Clownselors, Medical Clown, Trainer
Abhishek Kant
Founder GTM Catalyst
Vishnu Saran
Founder & CEO VoiceQube
Sandeep Soni
Founder & CEO Deccansoft, Microsoft Certified Trainer
Parveen Malik
AVP InfoSec & Vulnerability Management, Information Security Expert
Nitin Pandit
Microsoft MVP, Developer Evangelist, Author
Niloshima Srivastava
C# Corner MVP, Tech Architect, Trainer, Blogger
Bala Chirtsabesan
Senior Software Engineer at Microsoft, Author
Manoj Mittal
Sr. Technical Architect, C# Corner MVP, Author
Chandni Di
Co-Founder Voice of Slum
Vithal Wadje
Technical Lead, Microsoft MVP, Author
Shivam Ahuja
Founder SkillCircle, Business Mentor
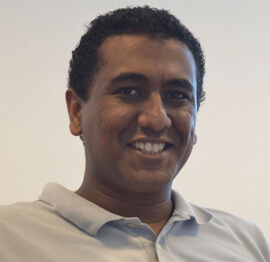
Chervine Bhiwoo
Solution Architect, Microsoft MVP, Author
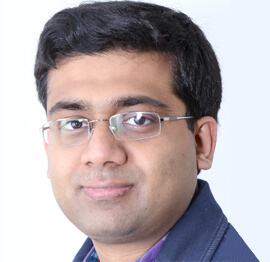
Saurabh Jain
Vice President Paytm, Founder Fun2Do Labs, Author
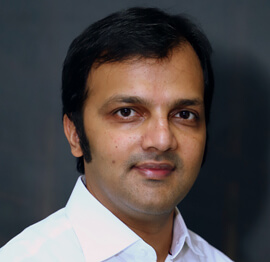
Vinay Solanki
Head IoT at Lenovo, Founder IoT-NCR
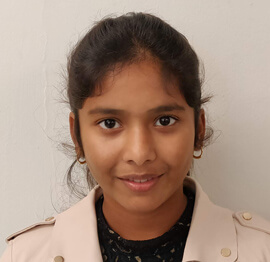
Anshu kumari
Founder Blockchainkids, Inventor, Trainer
Amit Singal
CEO Startup Buddy
Dev Pratap
Co-Founder & CEO Voice of Slum
Amey Vartak
Technology Consultant, Full Stack Developer, C# Corner MVP, Author
Viswanatha Swamy
Principal Software Engineer, C# Corner MVP, Author
Sanket Verma
Research Engineer @ Ballistics (Forensics) and Chair, PyData Delhi
Sourabh Somani
Lead Developer, Microsoft MVP, Author
Abhishek Mishra
Software Architect, C# Corner MVP, Author
Siddharth Vaghasia
Technical Consultant, C# Corner MVP, Blogger
Bassam Alugili
Senior Software Specialist, Database Expert
S Ravi Kumar
Solution Architect, C# Corner MVP, Author
Sundaram Subramanian
Full Stack Developer, C# Corner MVP, Speaker
Deepesh Somani
Solution Architect, Microsoft MVP, Author
Debasis Saha
Technical Project Manager, C# Corner MVP, Blogger, Author
Vipul Jain
Software Architect, C# Corner MVP, Author
Akshay Patel
Technical Architect, Microsoft Certified Trainer, C# Corner MVP, Author
Stephen Simon
RPA Developer, Evangelist, Author
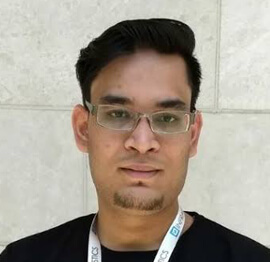
Vivek Sharma
Founder Kingster636, AR/VR Specialist
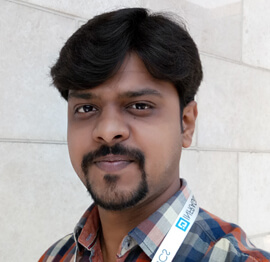
Jeetendra Gund
Technical Lead, C# Corner MVP, Author
Sujal Beniwal
AI Enthusiast, Student
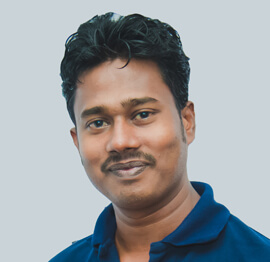
M Viknaraj
Microsoft MVP, Azure Architect, Author
Prasham Sabadra
Software Architect, C# Corner MVP, Trainer, Author
Aakash Maurya
Senior Developer, C# Corner MVP, Speaker
Ankit Sharma
Senior Software Engineer, C# Corner MVP, Author
Mangesh Gaherwar
Team Lead, C# Corner MVP, Author
Viral Jain
Technical Consultant, C# Corner MVP, Author
Bhasker Das
Solution Architect, Evangelist
Manish Dwivedi
Associate Project Manager
Ck Nitin
Programmer, Author
Rohit Gupta
Technical Trainer, Author
Manish Tewatia
Full-stack Marketer, UX Designer
Bhavya Gaur
Technical Illustrator
Rohit Tomar
SEO/SMO Expert
Web Track
Cloud & Data Track
Dev Track
Registration & Breakfast
Future of Desktop Apps with JS (ElectronJs)
Nitin Pandit
Building Serverless Microservices Using Microsoft Azure
Vithal Wadje
Innovating RPA: A Robot for Every Person
Stephen Simon
Managing Cloud Storage Accounts using Logic Apps
Viknaraj Manogararajah
Data visualization using Python
Sekhar Srinivasan
Going Cross platform with AR Foundation
Vivek Sharma
Keynote
Managing your Azure dependencies in ASP.NET Core apps using VS
Bala Chirtsabesan
Securing Applications on Intelligent Azure
Abhishek Mishra
Getting started with Blazor the Framework of Future
S Ravi Kumar
Lunch
Build Progressive Web Apps using Angular 9
Debasis Saha
Build and deploy to any platform using Azure DevOps
Chervine Bhiwoo
Deep Dive in Azure Service Bus
Akshay Patel
Build a Native Mobile Application using React Native and JavaScript
Joseph Guadagno
Making sense of Web Job, Web Job SDK and Functions in Azure
Prakash Tripathi
CloudFront Distribution in AWS
Viral Jain
Tea Break
Introduction to PowerBI
Aakash Maurya
Build Advanced SPFx solutions with React and Graph API
Siddharth Vaghasia
Build Business Intelligence Analyst (BIA) Skills
Sundaram Subramanian
Deep dive of Power Platform – AI BUILDER
Prasham Sabadra
Panel 1
What's new in SharePoint development
Vipul Jain
Build a SSO (Single Sign On) based Native JavaScript application with Microsoft Identity within 10 minutes
Manoj Mittal
Panel 2
Applications and working of AI
Veena Sarda
Deploying serverless API's with .Net core 3.0 on AWS & Azure
Amey Vartak
Panel 3
Blockchain with .NET Core (Ark)
Anshu Kumari
Closing Note & Prize Distribution
Dev Track
Cloud Track
Architecture Track
Emerging Tech Track
Registration & Breakfast
Creating Full-Stack Web Apps Using Server-Side Blazor
Ankit Sharma
Real time face recognition with MS Cognitive Services
Niloshima Srivastava
Building Scalable APIs with GraphQL
Jeetendra Gund
Future of development with AI and Blockchain
Navdeep Garg
Debugging Tips and Tricks with Visual Studio 2019
Joseph Guadagno
Azure Containers
Abhishek Kant
Enterprise Architecture
Naveen Sharma
Bot Framework - learn it fast and look like a boss!
Allen O’Neill
Keynote
.Net Core & C# 8 Performance
David McCarter
Working with Azure kubernetes services
Ritesh Modi
Becoming an Architect
Vidyavrat Agarwal
Why Techies Need to Learn Product Management
Saurabh Jain
Lunch
Build a rules engine in .Net Core
Sanjay Vyas
Building CI and CD Pipeline using Azure DevOps
Sandeep Soni
Entity Framework Core - Tips and Tricks, Performance Optimization, and Tuning
Bassam Alugili
Hacking your way into Data Science
Sanket Verma
Speed up your .Net Core Website
Sourabh Somani
Azure
Magnus Mårtensson
Demystifying Open Distro for Elasticsearch
Suman Debnath
Future of Data
Shivam Ahuja
Tea Break
gRPC with C# and .Net Core
Mangesh Gaherwar
Panel 1
Essentials of Cloud security
Parveen Malik
Power platform and Dynamics 365
Deepesh Somani
Microservices - the gRPC Way
Viswanatha Swamy
Panel 2
Reserved
Reserved
Closing Note & Prize Distribution
How to Use Azure Data Lake for Big Data Analytics
Organizations generate data from applications, websites, connected devices, business systems, and customer interactions. When these sources produce terabytes or petabytes of structured and unstructured information, traditional databases can become expensive and difficult to scale. Azure Data Lake provides a central storage foundation for collecting, organizing, and analyzing this information.
Azure Data Lake Storage, particularly the Gen2 architecture, combines the scale and durability of Azure Blob Storage with capabilities designed for analytics workloads. It can store raw files, transformed datasets, logs, documents, images, and event data while integrating with services such as Azure Data Factory, Azure Synapse Analytics, Azure Databricks, HDInsight, and Power BI.
A successful data lake implementation requires more than uploading files to cloud storage. Teams need a logical structure, reliable ingestion pipelines, appropriate file formats, strong access controls, and a repeatable approach to processing data. The following workflow explains how these elements work together in a practical big data analytics environment.
Understand The Data Lake Architecture
Azure Data Lake Storage Gen2 is built on Azure Blob Storage and adds a hierarchical namespace. This namespace allows files and directories to be managed in a way that resembles a conventional file system. Directory-level operations are faster and easier to control, which is particularly useful when analytical datasets contain millions of objects.
A typical lake contains several data zones. A landing or raw zone stores information in its original form. A curated zone contains cleaned, validated, and standardized data. An analytics or serving zone holds datasets optimized for reporting, machine learning, or operational analysis. Separating these stages helps preserve source data while making transformations traceable.
The storage account is the primary Azure resource, while containers provide logical boundaries for data. Within each container, directories can be organized by source, subject, date, region, or processing stage. A consistent naming convention is essential because poorly organized paths make discovery, permissions, and automated processing harder.
The lake can support both batch and streaming workloads. Batch files may arrive through scheduled exports, while event data can be captured through Azure Event Hubs or IoT services. Azure Data Factory, Synapse pipelines, and other orchestration tools can then move and transform the data according to business requirements.
Design A Reliable Storage Strategy
Before creating pipelines, define what data the lake will contain and how users will consume it. Identify source systems, expected data volumes, update frequency, retention requirements, and sensitivity classifications. This assessment determines storage paths, processing tools, partitioning methods, and security policies.
File format has a major effect on analytical performance. CSV and JSON are convenient for ingestion and inspection, but they are verbose and require more storage and processing. Columnar formats such as Parquet are usually better for analytics because engines can read only the required columns and apply compression efficiently. Avro is also useful when schema evolution and record-oriented processing are important.
Partitioning reduces the amount of data scanned during a query. A transaction dataset, for example, could be organized by year, month, and region. However, excessive partitioning creates many small files and increases metadata overhead. A practical design balances query filtering with manageable file sizes and a sensible directory structure.
The raw zone should generally be immutable. Instead of overwriting source files, retain original extracts and record ingestion timestamps or batch identifiers. Curated data can be rebuilt from the raw layer when business rules change. This approach improves auditability and helps analysts investigate discrepancies between source systems and reports.
Ingest And Transform Big Data
Azure Data Factory provides connectors and pipeline activities for importing data from databases, SaaS applications, file systems, and other cloud services. Copy activities can place source data in the lake, while mapping data flows can perform transformations without requiring every operation to be written as custom code.
For large-scale engineering, Azure Databricks offers Apache Spark clusters for distributed processing. Spark can cleanse records, join large datasets, calculate aggregations, and write results in Parquet or Delta-compatible formats. Azure HDInsight provides another option for managed open-source frameworks, including Spark and Hadoop technologies.
Streaming pipelines require a different design. Event Hubs can capture high-volume telemetry or application events, while Stream Analytics can filter, aggregate, and route data in near real time. Streaming outputs may be written to Data Lake Storage for historical analysis, sent to dashboards, or forwarded to downstream applications.
Transformations should be separated into clear stages. Validation can identify missing fields, invalid dates, duplicate records, or unexpected values. Standardization can align time zones, units of measurement, customer identifiers, and naming conventions. Enrichment can add reference data such as geography, product categories, or organizational ownership.
Select The Right Analytics Engine
Different workloads call for different Azure services. Azure Synapse Analytics supports SQL-based querying, data warehousing, Spark processing, and pipeline orchestration in a unified analytics environment. Serverless SQL is useful for querying files directly in the lake without maintaining a dedicated warehouse, while dedicated SQL pools are suited to predictable, high-volume warehouse workloads.
Azure Databricks is appropriate when teams need advanced Spark capabilities, collaborative notebooks, data engineering, or machine learning workflows. Analysts and developers can use Python, SQL, Scala, or R to process distributed datasets. This flexibility is valuable when transformations exceed the capabilities of simple SQL queries.
Power BI can connect to prepared datasets or analytical models for dashboards and reports. It is usually better to expose curated data rather than allow every report to query raw files independently. A semantic model can provide consistent definitions for revenue, active users, service levels, or other key metrics.
The following comparison illustrates how common Azure tools fit into a data lake analytics workflow:
| Azure service | Primary role | Suitable workload | Typical output |
|---|---|---|---|
| Azure Data Factory | Data movement and orchestration | Scheduled ingestion and transformation | Files, pipelines, curated datasets |
| Azure Data Lake Storage Gen2 | Scalable analytical storage | Structured and unstructured data | Raw, curated, and serving zones |
| Azure Synapse Analytics | SQL, warehousing, and Spark analytics | Interactive queries and enterprise reporting | Tables, views, analytical models |
| Azure Databricks | Distributed data engineering and machine learning | Complex transformations and predictive analysis | Refined files, models, feature datasets |
| Azure Stream Analytics | Real-time event processing | Telemetry, monitoring, and streaming metrics | Alerts, dashboards, lake files |
| Power BI | Visualization and business intelligence | Self-service and governed reporting | Reports, dashboards, scorecards |
Protect, Govern, And Monitor Data
Security should be designed before data is loaded. Azure role-based access control can manage permissions at the storage account, container, or directory level. Access control lists provide more granular file and folder permissions, which can help separate responsibilities among data engineers, analysts, applications, and administrators.
Use managed identities wherever possible so services can authenticate without storing passwords or connection strings in code. Encryption at rest is provided by Azure Storage, while secure network configuration can include private endpoints, firewall rules, and virtual network integration. Sensitive information should be classified and handled according to organizational and regulatory requirements.
Governance makes the lake understandable and trustworthy. Maintain metadata describing each dataset, its owner, source, refresh frequency, schema, sensitivity, and intended use. A catalog such as Microsoft Purview can support discovery and lineage across data sources, pipelines, and analytical assets.
Monitoring should cover both infrastructure and data quality. Track storage growth, pipeline duration, failed activities, query performance, cluster utilization, and access patterns. Add validation checks for row counts, null rates, duplicate keys, schema changes, and freshness. Azure Monitor and Log Analytics can centralize operational telemetry and support alerting.
Improve Performance And Control Costs
Cloud storage is economical, but inefficient processing can still produce substantial costs. Store data in compressed formats and avoid repeatedly scanning raw files. Partition datasets around common filter columns such as event date, tenant, or geographic region. For frequently queried data, create aggregated or optimized serving datasets rather than running expensive transformations for every report.
Small files are a common performance problem. Streaming jobs and frequent incremental writes can create thousands of tiny objects, increasing metadata operations and slowing Spark or SQL queries. Periodically compact these files into larger, well-sized objects while preserving partition boundaries and processing history.
Compute should be matched to workload patterns. Use serverless querying for occasional exploration, autoscaling Spark clusters for variable processing demand, and dedicated resources when predictable performance is more important than elasticity. Shut down or scale down development clusters when they are idle, and use separate environments for development, testing, and production.
Lifecycle management can move older data to cooler storage tiers or delete records after the approved retention period. Retention rules should account for legal, audit, and analytical requirements. Cost reports and budgets can reveal unexpected growth in storage, data transfer, or compute consumption before it becomes a major issue.
Build A Practical Implementation Plan
A focused pilot is often more effective than attempting to migrate every source system at once. Select a business case with measurable value, such as customer behavior analysis, equipment monitoring, sales forecasting, or application log analysis. Begin with a limited dataset and define success criteria for data freshness, query speed, quality, and reporting usefulness.
A repeatable implementation can follow these steps:
- Create a secure Azure subscription structure and separate development, test, and production resources.
- Establish raw, curated, and serving zones with documented naming and partitioning conventions.
- Ingest a representative source through Data Factory, Event Hubs, or another suitable connector.
- Convert and validate data using Synapse, Databricks, or a Spark-based processing job.
- Apply RBAC, ACLs, managed identities, encryption, network controls, and metadata ownership.
- Connect a governed dataset to Power BI and measure performance, reliability, and user adoption.
Automate infrastructure and deployment wherever possible. Templates, source control, and continuous integration pipelines make it easier to reproduce storage accounts, permissions, linked services, notebooks, and SQL objects. Parameterized pipelines can support multiple environments without copying and manually editing production workflows.
Document decisions as the platform evolves. Record why a file format was selected, how a dataset is partitioned, which teams own it, and what constitutes a successful data-quality check. Clear documentation reduces dependence on individual engineers and gives analysts confidence that the numbers behind their reports are reliable.
Azure Data Lake becomes most valuable when it turns scattered information into a governed analytical asset. Start with a well-defined use case, preserve raw data, use scalable processing engines, and make security and quality part of the pipeline itself. Explore the conference sessions and expert perspectives available through the C# Corner Annual Conference 2020 platform, then apply these Azure data lake practices to a focused analytics project that can grow with your organization.
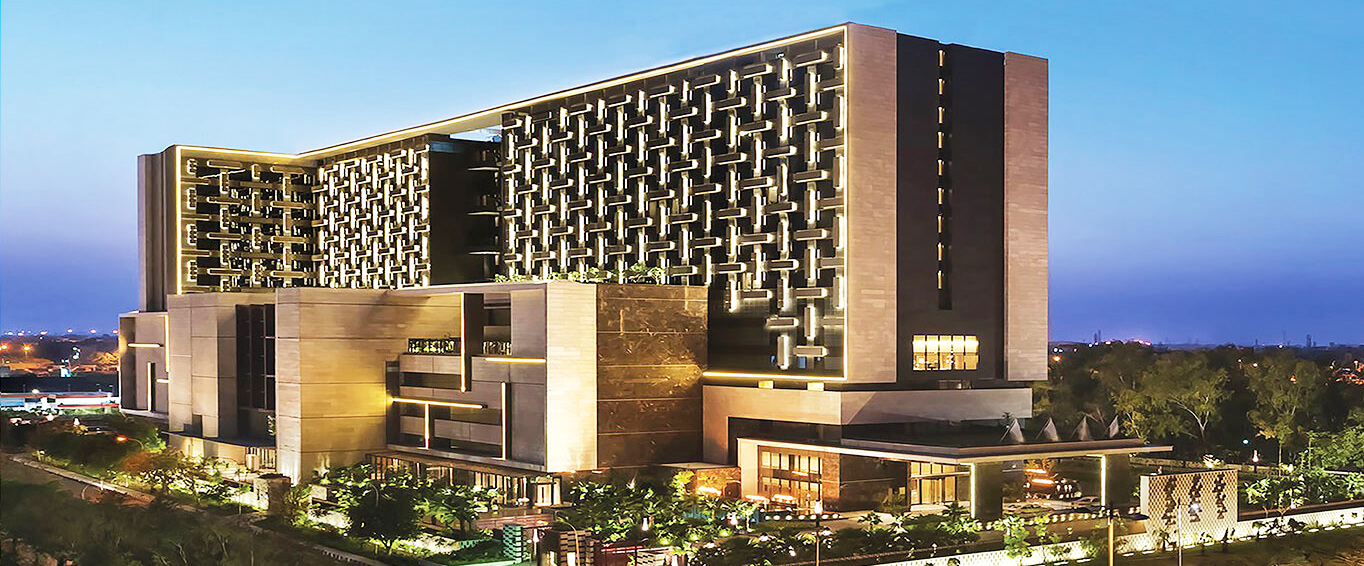
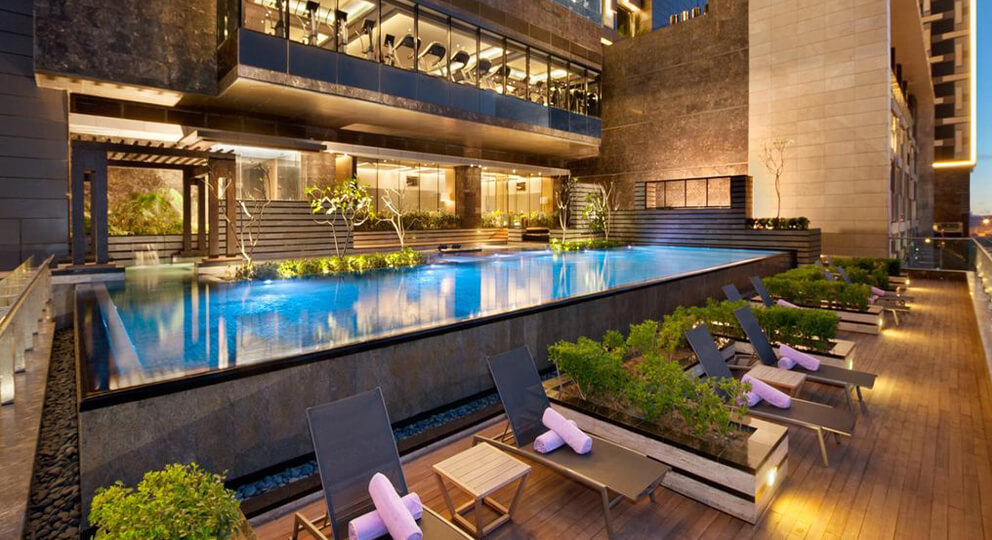
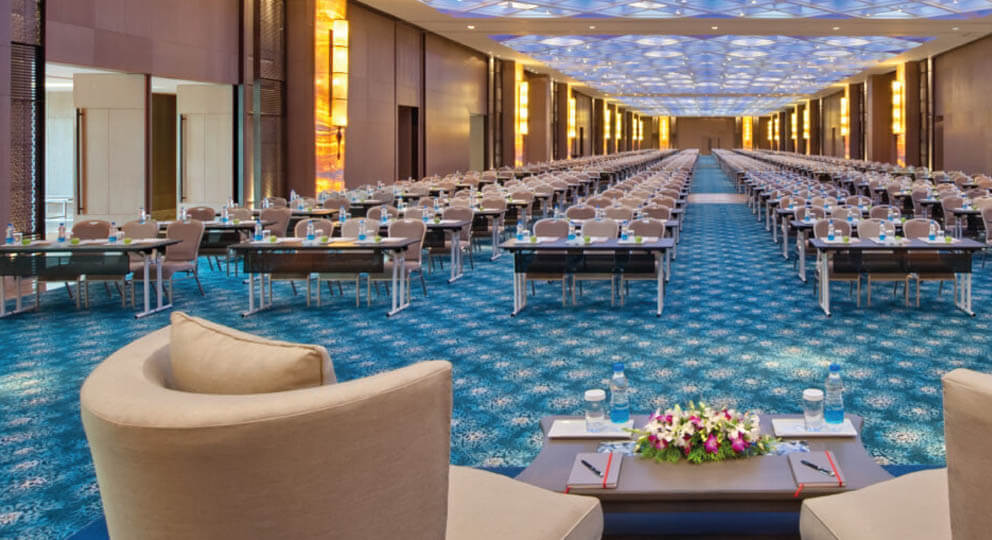
1, CBD, Maharaj Surajmal Road, Near Yamuna Sports Complex, Delhi, 110032
GENERAL QUERIES
Manish Tewatia
manish@csharpcon.com
+91-9718-431-042
TICKET QUERIES
Atul Gupta
conference@csharpcon.com
+91-9910-125-804