Presents
Magnus Mårtensson
Microsoft Regional Director, Azure MVP, CEO Loftysoft
Avirag Jain
Director & CTO R Systems
Mahesh Chand
Founder C# Corner, CEO Mindcracker
Chris Gali
CEO & Co-Founder Graphite
Subinder Khurana
Chief Architect StoryProcess, Founder NASSCOM DeepTech Club
Bryan Rishforth
Investor, Chairman Graphite
Bryn Everson
Director Biz Dev Graphite
Raj Tiwari
Digital Transformation Leader, Futurist and Visionary
Joseph Guadagno
Microsoft MVP, Lead Quicken Loans
Nikita Sachdev
Entrepreneur, Blockchain Enthusiast & Advisor, Social Media Influencer
Doug Wagner
COO & Founder Adapt Technical Group
Ritesh Modi
Architect, Senior Evangelist, Cloud Architect
Crystal Wenrick
Director Communications Mindcracker
Allen O’Neill
Microsoft MVP, Consulting Engineer/Architect
Praveen Kumar
CEO MCN Solutions
Chris Love
Founder Love2Dev, Microsoft MVP, Author
Sanjay Vyas
Microsoft Regional Director, Microsoft MVP, Founder & CEO SkillLabs Technologies
Veena Sarda
Deep Learning Consultant, Author
Sekhar Srinivasan
C# Corner MVP, Microsoft Certified Trainer, Pluralsight Author
Lalit Bansal
Founder & CEO - EIY SYS
Navdeep Garg
CEO Revinfotech
Prakash Tripathi
Tech Manager/Leader, Microsoft MVP, Blogger
Bhavna Jain
Breakthrough Consultant
Naveen Sharma
Enterprise Architect, Leadership Coach, Author
Vidya Vrat Agarwal
Principal Architect, Microsoft MVP, Author
Sheetal Agarwal
Founder Clownselors, Medical Clown, Trainer
Abhishek Kant
Founder GTM Catalyst
Vishnu Saran
Founder & CEO VoiceQube
Sandeep Soni
Founder & CEO Deccansoft, Microsoft Certified Trainer
Parveen Malik
AVP InfoSec & Vulnerability Management, Information Security Expert
Nitin Pandit
Microsoft MVP, Developer Evangelist, Author
Niloshima Srivastava
C# Corner MVP, Tech Architect, Trainer, Blogger
Bala Chirtsabesan
Senior Software Engineer at Microsoft, Author
Manoj Mittal
Sr. Technical Architect, C# Corner MVP, Author
Chandni Di
Co-Founder Voice of Slum
Vithal Wadje
Technical Lead, Microsoft MVP, Author
Shivam Ahuja
Founder SkillCircle, Business Mentor
Chervine Bhiwoo
Solution Architect, Microsoft MVP, Author
Saurabh Jain
Vice President Paytm, Founder Fun2Do Labs, Author
Vinay Solanki
Head IoT at Lenovo, Founder IoT-NCR
Anshu kumari
Founder Blockchainkids, Inventor, Trainer
Amit Singal
CEO Startup Buddy
Dev Pratap
Co-Founder & CEO Voice of Slum
Amey Vartak
Technology Consultant, Full Stack Developer, C# Corner MVP, Author
Viswanatha Swamy
Principal Software Engineer, C# Corner MVP, Author
Sanket Verma
Research Engineer @ Ballistics (Forensics) and Chair, PyData Delhi
Sourabh Somani
Lead Developer, Microsoft MVP, Author
Abhishek Mishra
Software Architect, C# Corner MVP, Author
Siddharth Vaghasia
Technical Consultant, C# Corner MVP, Blogger
Bassam Alugili
Senior Software Specialist, Database Expert
S Ravi Kumar
Solution Architect, C# Corner MVP, Author
Sundaram Subramanian
Full Stack Developer, C# Corner MVP, Speaker
Deepesh Somani
Solution Architect, Microsoft MVP, Author
Debasis Saha
Technical Project Manager, C# Corner MVP, Blogger, Author
Vipul Jain
Software Architect, C# Corner MVP, Author
Akshay Patel
Technical Architect, Microsoft Certified Trainer, C# Corner MVP, Author
Stephen Simon
RPA Developer, Evangelist, Author
Vivek Sharma
Founder Kingster636, AR/VR Specialist
Jeetendra Gund
Technical Lead, C# Corner MVP, Author
Sujal Beniwal
AI Enthusiast, Student
M Viknaraj
Microsoft MVP, Azure Architect, Author
Prasham Sabadra
Software Architect, C# Corner MVP, Trainer, Author
Aakash Maurya
Senior Developer, C# Corner MVP, Speaker
Ankit Sharma
Senior Software Engineer, C# Corner MVP, Author
Mangesh Gaherwar
Team Lead, C# Corner MVP, Author
Viral Jain
Technical Consultant, C# Corner MVP, Author
Bhasker Das
Solution Architect, Evangelist
Manish Dwivedi
Associate Project Manager
Ck Nitin
Programmer, Author
Rohit Gupta
Technical Trainer, Author
Manish Tewatia
Full-stack Marketer, UX Designer
Bhavya Gaur
Technical Illustrator
Rohit Tomar
SEO/SMO Expert
Web Track
Cloud & Data Track
Dev Track
Registration & Breakfast
Future of Desktop Apps with JS (ElectronJs)
Nitin Pandit
Building Serverless Microservices Using Microsoft Azure
Vithal Wadje
Innovating RPA: A Robot for Every Person
Stephen Simon
Managing Cloud Storage Accounts using Logic Apps
Viknaraj Manogararajah
Data visualization using Python
Sekhar Srinivasan
Going Cross platform with AR Foundation
Vivek Sharma
Keynote
Managing your Azure dependencies in ASP.NET Core apps using VS
Bala Chirtsabesan
Securing Applications on Intelligent Azure
Abhishek Mishra
Getting started with Blazor the Framework of Future
S Ravi Kumar
Lunch
Build Progressive Web Apps using Angular 9
Debasis Saha
Build and deploy to any platform using Azure DevOps
Chervine Bhiwoo
Deep Dive in Azure Service Bus
Akshay Patel
Build a Native Mobile Application using React Native and JavaScript
Joseph Guadagno
Making sense of Web Job, Web Job SDK and Functions in Azure
Prakash Tripathi
CloudFront Distribution in AWS
Viral Jain
Tea Break
Introduction to PowerBI
Aakash Maurya
Build Advanced SPFx solutions with React and Graph API
Siddharth Vaghasia
Build Business Intelligence Analyst (BIA) Skills
Sundaram Subramanian
Deep dive of Power Platform – AI BUILDER
Prasham Sabadra
Panel 1
What's new in SharePoint development
Vipul Jain
Build a SSO (Single Sign On) based Native JavaScript application with Microsoft Identity within 10 minutes
Manoj Mittal
Panel 2
Applications and working of AI
Veena Sarda
Deploying serverless API's with .Net core 3.0 on AWS & Azure
Amey Vartak
Panel 3
Blockchain with .NET Core (Ark)
Anshu Kumari
Closing Note & Prize Distribution
Dev Track
Cloud Track
Architecture Track
Emerging Tech Track
Registration & Breakfast
Creating Full-Stack Web Apps Using Server-Side Blazor
Ankit Sharma
Real time face recognition with MS Cognitive Services
Niloshima Srivastava
Building Scalable APIs with GraphQL
Jeetendra Gund
Future of development with AI and Blockchain
Navdeep Garg
Debugging Tips and Tricks with Visual Studio 2019
Joseph Guadagno
Azure Containers
Abhishek Kant
Enterprise Architecture
Naveen Sharma
Bot Framework - learn it fast and look like a boss!
Allen O’Neill
Keynote
.Net Core & C# 8 Performance
David McCarter
Working with Azure kubernetes services
Ritesh Modi
Becoming an Architect
Vidyavrat Agarwal
Why Techies Need to Learn Product Management
Saurabh Jain
Lunch
Build a rules engine in .Net Core
Sanjay Vyas
Building CI and CD Pipeline using Azure DevOps
Sandeep Soni
Entity Framework Core - Tips and Tricks, Performance Optimization, and Tuning
Bassam Alugili
Hacking your way into Data Science
Sanket Verma
Speed up your .Net Core Website
Sourabh Somani
Azure
Magnus Mårtensson
Demystifying Open Distro for Elasticsearch
Suman Debnath
Future of Data
Shivam Ahuja
Tea Break
gRPC with C# and .Net Core
Mangesh Gaherwar
Panel 1
Essentials of Cloud security
Parveen Malik
Power platform and Dynamics 365
Deepesh Somani
Microservices - the gRPC Way
Viswanatha Swamy
Panel 2
Reserved
Reserved
Closing Note & Prize Distribution
Designing scalable data pipelines with Azure Data Factory
Modern applications generate data continuously from transactional systems, SaaS platforms, IoT devices, APIs, files, and event streams. Turning that information into reliable business insight requires more than a scheduled copy job. A production-grade data pipeline must manage changing schemas, uneven workloads, failures, security boundaries, and the growing volume of historical data.
Azure Data Factory provides a managed environment for building, scheduling, monitoring, and governing these workflows. It can move data between cloud and on-premises systems, transform information through mapping data flows or external compute services, and coordinate activities across an enterprise data platform.
The strongest implementations treat ADF as an orchestration layer rather than a single-purpose ETL tool. Pipeline design decisions made early—such as how parameters, triggers, retries, partitions, and metadata are handled—determine whether a solution remains maintainable as data sources and reporting requirements expand.
Start with a pipeline architecture
A scalable Azure data integration solution usually separates ingestion, transformation, storage, and consumption. Raw data should first land in an immutable zone, often Azure Data Lake Storage Gen2, before it is cleansed or reshaped. This preserves the original payload for auditing, replay, and future use cases.
A layered lake architecture makes the flow easier to reason about. The raw or bronze layer contains source-aligned data, the standardized or silver layer applies validation and common formats, and the curated or gold layer presents analytics-ready entities. Each layer can have its own retention policy, security controls, and quality checks.
Azure Data Factory coordinates these stages through pipelines, linked services, datasets, activities, and triggers. Linked services define connections to systems such as SQL Database, Blob Storage, Snowflake, REST endpoints, or SAP. Datasets describe the structure or location of data, while activities perform actions such as copying, executing SQL, calling notebooks, or running data flows.
The architecture should also distinguish control flow from data movement. ADF is effective at determining what should run, when it should run, and what happens after success or failure. For intensive transformations, Azure Databricks, Synapse Analytics, SQL pools, or serverless processing may provide better performance and cost control than performing every operation inside a single orchestration pipeline.
Build for metadata-driven ingestion
Hard-coding one pipeline for every table, file, or source system creates duplication and increases operational risk. A metadata-driven design stores configuration in a control table or configuration file. Typical metadata includes source connection, object name, destination path, load type, watermark column, primary key, partition strategy, and expected schedule.
A generic pipeline can read this configuration with a Lookup activity and pass each row into a ForEach activity. Parameters then determine which source object is queried and where its output is stored. This approach allows an onboarding process to add a new entity by registering metadata instead of duplicating pipeline logic.
Incremental loading is central to scalable ingestion. A watermark based on a modified timestamp, increasing identifier, or change tracking token allows the pipeline to retrieve only records added or changed since the previous successful run. The current watermark should be recorded transactionally so that a failed execution does not advance the state prematurely.
For sources that support it, change data capture can reduce query pressure and preserve deletes. Where CDC is unavailable, a carefully designed high-water mark query may be sufficient. Pipelines should account for late-arriving records, clock differences, and updates that occur while a batch is running. A small overlap window can improve completeness, provided downstream processing is idempotent.
Manage performance, parallelism, and cost
Scalability is not achieved simply by increasing concurrency. An ADF pipeline must balance parallel execution against source-system limits, integration runtime capacity, destination throughput, and cloud spending. Running hundreds of copy activities simultaneously may shorten one stage while overwhelming a database or causing throttling.
Partitioning is one of the most effective performance techniques. Large tables can be divided by date, key range, or a source-supported partition column, allowing multiple slices to load concurrently. File-based workloads benefit from sensible folder partitioning, such as year, month, day, or business region. Partition boundaries should produce reasonably even workloads rather than leaving one oversized slice to run after all others finish.
The integration runtime is another important design choice. Azure integration runtime is suitable for cloud data movement, while a self-hosted integration runtime can connect securely to private networks and on-premises systems. Teams should monitor queue time, throughput, CPU utilization, memory, and network behavior before changing capacity or parallelism settings.
Copy activity metrics help identify whether a bottleneck originates in the source, network, sink, or transformation stage. Compression, column selection, file format, and batch size also affect performance. Columnar formats such as Parquet are generally preferable for analytical workloads because they reduce storage and scanning costs, especially when paired with partition pruning.
Make orchestration reliable
A dependable pipeline assumes that transient failures will occur. Network interruptions, API throttling, temporary service unavailability, expired credentials, and locked source tables are normal operating conditions in distributed systems. Retry policies with exponential backoff can resolve temporary issues without requiring manual intervention.
Retries must be paired with idempotency. If a copy operation is repeated, it should not silently create duplicate records. Common strategies include writing to a temporary location and committing only after validation, using deterministic file names, loading into staging tables, or applying merge logic keyed by a business identifier.
Dependency management should express the actual business flow. A downstream transformation should run only after all required ingestion activities succeed. A validation branch can route incomplete or malformed data to quarantine storage while allowing independent entities to continue. Execute Pipeline activities help divide a large solution into reusable child pipelines for ingestion, quality checks, notification, and publication.
Operational visibility needs to be designed rather than added later. ADF monitoring provides run history, activity status, duration, and error details, while Azure Monitor and Log Analytics support alerts and longer-term analysis. Include correlation identifiers, source names, batch identifiers, and row counts in logging so an operator can trace a record from ingestion through publication.
Secure data movement and deployment
Security begins with identity and network design. Managed identities reduce the need to store passwords in pipeline definitions, and Azure Key Vault can hold secrets that cannot be replaced with identity-based authentication. Role-based access control should grant each pipeline only the permissions required for its source, landing zone, and processing targets.
Private endpoints, managed virtual networks, firewall rules, and self-hosted integration runtimes help protect sensitive systems. Data movement should use encrypted connections, and storage accounts should enforce secure transfer and appropriate public access restrictions. Sensitive columns may require masking, tokenization, or restricted access in curated datasets.
Development, testing, and production should be separated through parameterized environments. Azure DevOps or GitHub can manage collaboration, branching, pull requests, and automated deployment. Infrastructure as code can provision storage, integration runtimes, Key Vault resources, monitoring components, and access policies consistently.
ADF supports publish and release workflows, but deployment discipline remains essential. Environment-specific values should be externalized rather than embedded in activities. A release should validate linked services, triggers, permissions, and integration runtimes before enabling scheduled execution. Version-controlled pipelines also make rollback and audit activities more predictable.
A well-designed data platform should align with broader application engineering practices. Teams building cloud-connected web solutions may find the enterprise frontend patterns useful when coordinating application behavior with asynchronous data availability, authentication, and reporting workflows.
Compare common loading patterns
The correct loading strategy depends on source capabilities, data volume, latency requirements, and the cost of reprocessing. Batch ingestion is often adequate for daily financial reporting, while operational dashboards may require near-real-time technologies such as Azure Event Hubs, Stream Analytics, or change feed processing alongside ADF.
ADF can support several patterns within the same platform. A full load is simple and useful for small reference entities, but it becomes expensive for large tables. An incremental load reduces work by using a watermark or change token. A hybrid approach may use an initial full load followed by incremental updates, with periodic reconciliation to detect drift.
| Loading pattern | Best fit | Main strengths | Main risks |
|---|---|---|---|
| Full load | Small tables and reference data | Simple logic and easy recovery | High source, network, and compute usage |
| Watermark-based incremental load | Systems with reliable timestamps or IDs | Efficient and straightforward to schedule | Missed changes if source metadata is unreliable |
| Change data capture | Databases that expose inserts, updates, and deletes | Preserves detailed change history | Requires source support and state management |
| File arrival ingestion | Reports, exports, and partner feeds | Works well with landing zones and event triggers | Duplicate or partial files need careful handling |
| Hybrid load and reconciliation | Critical enterprise entities | Balances efficiency with completeness checks | More metadata, validation, and operational complexity |
File arrival patterns should verify that a file is complete before processing. A producer may write a temporary file and rename it after completion, or publish a manifest containing expected files and sizes. Event-based triggers can reduce latency, but they should be combined with deduplication and replay handling.
For large analytical datasets, consider separating ingestion frequency from transformation frequency. Data can land frequently in the lake while downstream compaction or dimensional processing runs in controlled micro-batches. This reduces the number of small files and keeps compute usage aligned with actual business needs.
Apply quality controls and operating practices
Data quality checks should be explicit pipeline activities rather than informal assumptions. Useful checks include row counts, null rates, duplicate keys, referential integrity, accepted value ranges, schema compatibility, and freshness thresholds. A failed check should produce a clear status and preserve the offending data for investigation.
Schema evolution deserves special attention. New nullable columns may be safely accepted, while renamed or removed fields can break transformations and reports. Store schema versions with the ingested data, compare incoming structures with an approved contract, and use quarantine paths for incompatible changes. This protects downstream consumers from silent corruption.
Cost governance also belongs in daily operations. Set retention rules for raw and intermediate data, stop unused debug resources, and review pipeline frequency against actual business value. Monitoring should track activity duration, data volume, failed runs, retry counts, and compute consumption by domain or workload.
Practical standards make the platform easier for multiple teams to operate. Use consistent naming, parameter conventions, folder structures, error messages, and run identifiers. Keep pipelines small enough to test and reuse, but avoid excessive fragmentation that makes dependencies difficult to follow.
A focused implementation checklist can guide reviews before production release:
- Define source ownership, load frequency, latency expectations, and recovery objectives.
- Store connection details and secrets outside pipeline code, using managed identities where possible.
- Make ingestion reusable through parameters, metadata, watermarks, and controlled parallelism.
- Design every write operation for safe retry, replay, and duplicate prevention.
- Add quality checks, operational alerts, lineage details, and documented support procedures.
Turn the design into a production workflow
A strong Azure Data Factory solution grows from a representative use case rather than a collection of disconnected demonstrations. Start with one high-value data domain and model its complete journey: source extraction, raw landing, validation, transformation, curated publication, monitoring, and recovery.
Test realistic conditions before expanding the pattern. Include large volumes, slow sources, schema changes, duplicate files, missing partitions, expired credentials, partial failures, and reruns. Measure throughput and cost using production-like data, because a pipeline that works for a small development sample may behave very differently at enterprise scale.
Once the pattern is stable, publish reusable templates and metadata conventions for additional domains. Keep ownership clear for each source and curated dataset, and establish service-level expectations for freshness and incident response. Treat pipeline runs as observable production workloads with measurable reliability rather than invisible background tasks.
Explore the conference’s cloud and data sessions, then apply these principles in a working ADF project: define the landing architecture, implement metadata-driven ingestion, secure the connections, test failure recovery, and monitor each stage. A deliberately designed pipeline can turn Azure Data Factory from a collection of copy jobs into a dependable foundation for analytics, machine learning, and operational decision-making.
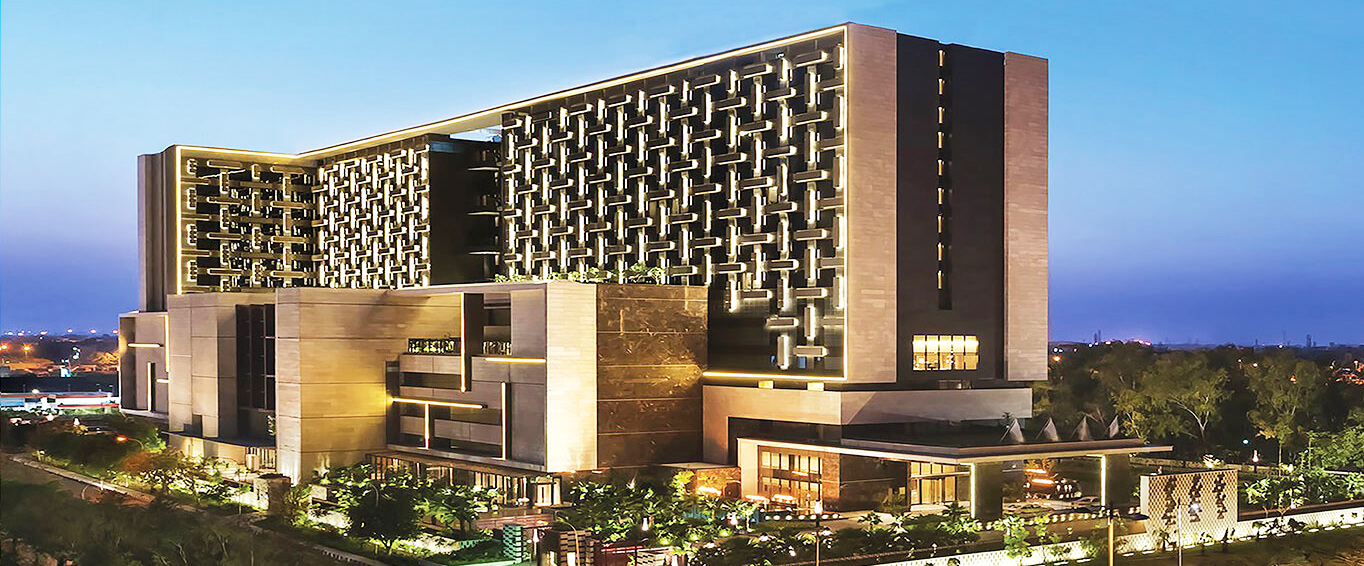
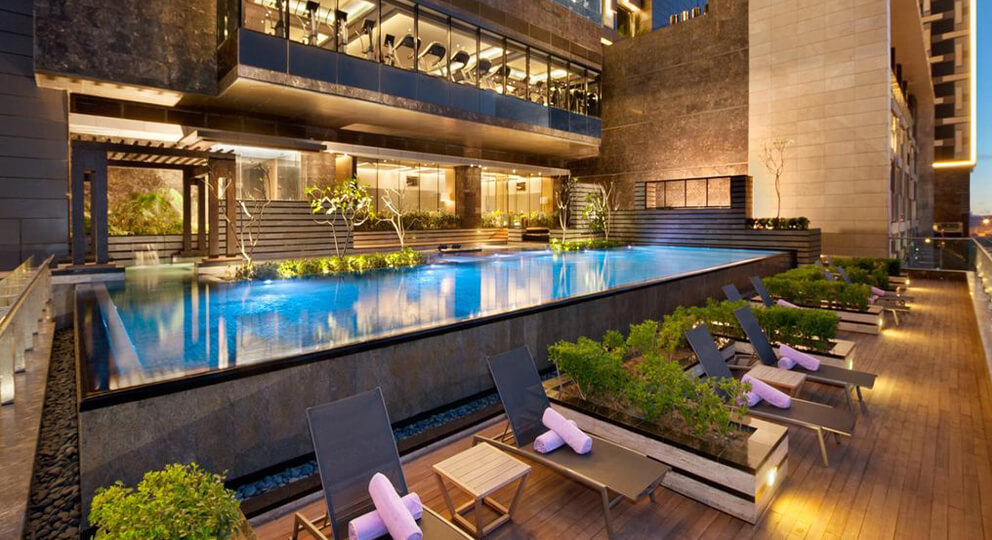
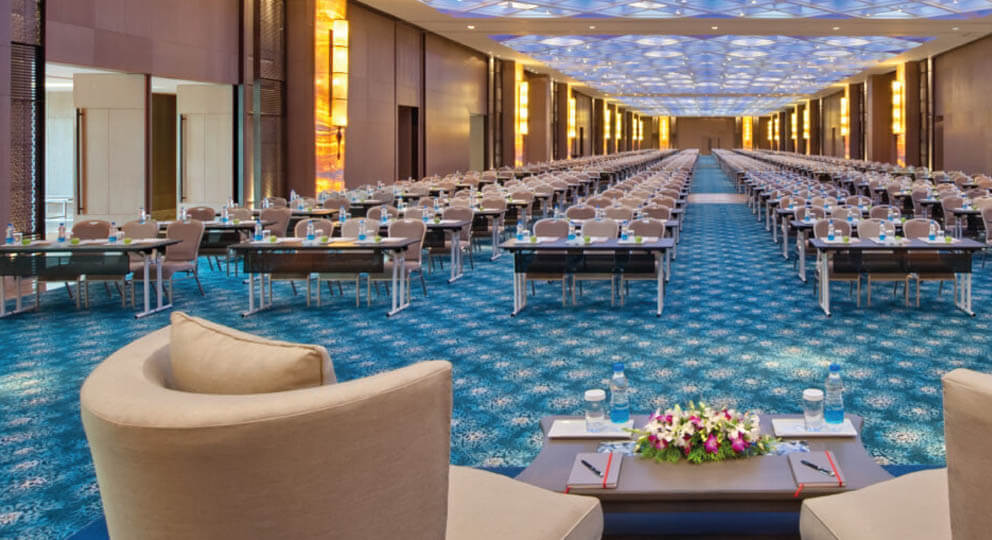
1, CBD, Maharaj Surajmal Road, Near Yamuna Sports Complex, Delhi, 110032
GENERAL QUERIES
Manish Tewatia
manish@csharpcon.com
+91-9718-431-042
TICKET QUERIES
Atul Gupta
conference@csharpcon.com
+91-9910-125-804